12.2 The exponential-family harmonium

Contrastive divergence learning (Eq. 12.3) goes some way toward ameliorating the third of the three disadvantages of EBMs enumerated at the outset of this chapter. We now turn to the second disadvantage: the lack of latent variables.

12.2.1 The EFH as a latent-variable model.

Recall from our introduction to latent-variable density estimation above, Section 8.2, one of the motivations for introducing latent variables into our density-estimation problem: they can provide flexibility in modeling the observed data. When we have, in addition, a notion of how these latent variables are (marginally) distributed, and how the observations are conditionally distributed given a setting of the latent variables—that is, when we have some idea of both p^⁢(𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}\right)} and p^(𝒚|𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}% \right)}—directed graphical models (and therefore EM-like learning procedures) are a natural choice. This usually occurs when the latent variables are semantically interpretable and correspond to named quantities. For example, in the (admittedly toy) problem in Fig. 3.2a, the prior is a Bernoulli distribution precisely because the hidden variable is taken to be the outcome of a(n unobserved) coin flip.

In order to introduce latent variables into EBMs, we now return to the undirected graphical model known as the exponential-family harmonium (EFH) (Section 4.2) [78]. We can contrast the EFH with the directed models considered heretofore by interpreting it as trading the assumption about the form of the prior, p^⁢(𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}\right)}, for one about the form of the posterior, p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}. But note that this is almost never done because we have any a priori domain knowledge about the posterior distribution. EBMs fall squarely in the group of models with non-semantic latent variables (which group also includes, of course, many modern directed graphical models, such as those discussed in Chapter 10).

Therefore, the form of the posterior for the EFH is selected mostly for mathematical convenience. Perhaps we require the hidden variables to have support in a certain set (e.g., the positive integers), but even this is uncommon. Most often, the individual elements of the vector of hidden units have no precise semantic content; rather, the vector as a whole represents no more than a kind of flexible set of parameters. After learning, they can be interpreted as detectors of “features” of the data, but there is still usually no a priori reason to assume that these features should be distributed according to p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}. That is one reason why the RBM is so much more common than other exponential-family harmoniums: a binary vector will generally be just as suitable to represent features as, say, a vector of positive integers. In this, EFHs have a strong kinship with deterministic neural networks.

In any case, we do specify a form for the posterior, p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}, at the expense of freedom to choose the prior, p^⁢(𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}\right)}. This makes inference trivial (no Bayes inversion is necessary), and is one of the primary appeals of the EFH. Unfortunately, we give up not only the freedom to specify, but also to take expectations under, and even to sample from, the prior. In this, the EFH is like other energy-based models. Indeed, all three of the marginal distribution of observations, p^⁢(𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}\right)}, the marginal distribution of latent variables, p^⁢(𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}\right)}, and the joint distribution of both, p^⁢(𝒙,𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{},{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}, are computable only up to an intractable normalizer. Being unable to sample from the prior rules out the ancestral sampling that directed models enjoy.

Is the price of the trade worthwhile? Learning in the EFH will require inference, naturally, but will also require an expectation under the intractable model joint distribution, and therefore encounters the same obstacles as in training generic EBMs. As with EBMs more generally, the intractable expectation under the model can be approximated with a sample average, but acquiring those samples is, as we have just noted, not trivial—again as in generic EBMs. On the other hand, sampling can be accelerated with block Gibbs sampling††margin: accelerated over what baseline? , and the loss can be approximated with the method of contrastive divergence, lately described (Section 12.1.2). The EFH also enjoys an even more remarkable property, which is the ability to be composed hierarchically, along with a guarantee that this improves learning (more precisely, it lowers a bound). We describe these models, called “deep belief networks (DBNs),” in Section 12.2.3.

12.2.2 Learning with exponential-family harmoniums

The loss gradient for EBMs with latent variables.

Rather than derive the learning rule just for the harmonium, we start with a generic Boltzmann distribution over observed variables 𝒀^{\bm{\hat{Y}}} and latent variables 𝑿^{\bm{\hat{X}}}:

equation (12.6) (12.6)
p^⁢(𝒙,𝒚;𝜽)=1Z⁢(𝜽)⁢exp⁡{−U^⁢(𝒙,𝒚,𝜽)},Z⁢(𝜽)=∑𝒙^∑𝒚^exp⁡{−U^⁢(𝒙^,𝒚^,𝜽)}.\begin{split}{\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{},{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{% \theta}}\right)}&{}=\frac{1}{Z(\bm{\theta})}\exp\mathopen{}\mathclose{{}\left% \{-\hat{U}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{},{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{},\bm{\theta}}% \right)}\right\},\\ Z(\bm{\theta})&{}=\sum_{\bm{\hat{x}}{}}\sum_{\bm{\hat{y}}{}}\exp\mathopen{}% \mathclose{{}\left\{-\hat{U}\mathopen{}\mathclose{{}\left(\bm{\hat{x}},\bm{% \hat{y}},\bm{\theta}}\right)}\right\}.\end{split}

Recall that this is also the generic form of distributions parameterized by undirected graphical models, although in this case we have made no assumptions about the underlying graph structure. Just as in EBMs without latent variables, without further constraints on the energy, the normalizer, Z⁢(𝜽)Z(\bm{\theta}), is intractable for sufficiently large 𝑿^{\bm{\hat{X}}} and 𝒀^{\bm{\hat{Y}}}, because the number of summands in Eq. 12.6 is exponential in dim(𝑿^)+dim(𝒀^)\dim\mathopen{}\mathclose{{}\left({\bm{\hat{X}}}}\right)+\dim\mathopen{}% \mathclose{{}\left({\bm{\hat{Y}}}}\right). In some special cases of continuous random variables, the calculation of the normalizer may reduce to tractable integrals, but these cases are exceptional.

The goal, as usual, is to minimize the relative entropy of the distributions of observed data, p⁢(𝒚){p\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}}\right)}, and of model observations, p^⁢(𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}\right)}. The method is to follow its gradient in parameter space. Recalling from Eq. 8.3:

equation (12.7) (12.7)
dd⁢𝜽⁢DKL⁡{p⁢(𝒀)∥p^⁢(𝒀;𝜽)}=𝔼𝑿^,𝒀⁢[−dd⁢𝜽⁢log⁡p^⁢(𝑿^,𝒀;𝜽)],{\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}}}}\operatorname*{\text{D}_{\text{% KL}}}\mathopen{}\mathclose{{}\left\{{p\mathopen{}\mathclose{{}\left({\bm{Y}}}% \right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{Y}};\bm{\theta}}% \right)}}\right\}=\mathbb{E}_{{\bm{\hat{X}}}{},{\bm{Y}}{}}{\mathopen{}% \mathclose{{}\left[-{\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}}}}\log{\hat{p}% \mathopen{}\mathclose{{}\left({\bm{\hat{X}}},{\bm{Y}};\bm{\theta}}\right)}}% \right]},

where the average is under the “hybrid” joint distribution p^(𝒙|𝒚;𝜽)p(𝒚){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}{p\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}}\right)}. This is the point at which we opted, when working with directed graphical models in Chapter 8, to use EM—i.e., to work directly with the generative joint distribution on the right-hand side of Eq. 12.7, and abandon the expectation under p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)} in favor of one under a (distinct) recognition model, pˇ(𝒙|𝒚){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}}\right)}. This reduces the problem to (repeatedly) fitting a fully observed joint p^⁢(𝒙,𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{},{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)} to data pˇ(𝒙|𝒚)p(𝒚){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}}\right)}{p\mathopen% {}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor% }{rgb}{.75,0,.25}\bm{y}}{}}\right)} (although this only minimizes an upper bound on the loss). It is appealing because we have in hand an expression for the generative joint but not for the generative posterior.

Here we are in roughly the opposite situation: the joint distribution is not tractable, due to the normalizer Z⁢(𝜽)Z(\bm{\theta}) (which, note well, is a function of the parameters we wish to optimize); but the posterior distribution p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)} is. We will therefore proceed by applying Eq. 12.7 directly to the Boltzmann distribution, Eq. 12.6, but expecting the intractable normalizer to block progress at some point. The derivation exactly parallels Eq. 12.2, the only difference being that the outer expectation is taken under p^(𝒙|𝒚;𝜽)p(𝒚){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}{p\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}}\right)} rather than just p⁢(𝒚){p\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}}\right)}. Therefore we obtain

equation (12.8) (12.8)
𝔼𝑿^,𝒀⁢[−dd⁢𝜽⁢log⁡p^⁢(𝑿^,𝒀;𝜽)]=𝔼𝑿^,𝒀⁢[∂U^∂𝜽⁢(𝒀,𝜽)]−𝔼𝑿^,𝒀^⁢[∂U^∂𝜽⁢(𝒀^,𝜽)].\begin{split}\mathbb{E}_{{\bm{\hat{X}}}{},{\bm{Y}}{}}{\mathopen{}\mathclose{{}% \left[-{\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}}}}\log{\hat{p}\mathopen{}% \mathclose{{}\left({\bm{\hat{X}}},{\bm{Y}};\bm{\theta}}\right)}}\right]}=% \mathbb{E}_{{\bm{\hat{X}}}{},{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\frac{% \partial{\hat{U}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{\theta}}}}\mathopen{}\mathclose{{}\left({% \bm{Y}},\bm{\theta}}\right)}\right]}-\mathbb{E}_{{\bm{\hat{X}}}{},{\bm{\hat{Y}% }}{}}{\mathopen{}\mathclose{{}\left[\frac{\partial{\hat{U}}}{\partial{{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\theta}}% }}\mathopen{}\mathclose{{}\left({\bm{\hat{Y}}},\bm{\theta}}\right)}\right]}.% \end{split}

In words, the gradient is equal to the difference between the expected energy gradient under two different distributions: the “hybrid joint distribution,” constructed by combining the data distribution (over 𝒀{\bm{Y}}) with the generative model’s posterior distribution (over 𝑿^{\bm{\hat{X}}}); and the complete generative model. Again, the second expectation is intractable, and even sample averages can be time-consuming.

The loss gradient for EFHs.

Now we make an assumption about the roles of 𝑿^{\bm{\hat{X}}} and 𝒀^{\bm{\hat{Y}}}. As we saw in Section 4.2, constraining the conditional distributions p^(𝒚|𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}% \right)} and p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)} to be (1) in exponential families and (2) consistent with each other implies that they take the form

equation (12.9) (12.9)
p^(𝒙|𝒚;𝜽)\displaystyle{\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};% \bm{\theta}}\right)}
=h⁢(𝒙)⁢exp⁡{(𝒃x^+𝐖y^⁢x^⁢𝑼⁢(𝒚))T⁢𝑻⁢(𝒙)−A⁢(𝜼⁢(𝒚))},\displaystyle{}=h({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{% rgb}{.75,0,.25}\bm{x}})\exp\mathopen{}\mathclose{{}\left\{\mathopen{}% \mathclose{{}\left(\bm{b}_{\hat{x}}+\mathbf{W}_{\hat{y}\hat{x}}{\bm{U}}({% \color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y% }})}\right)^{\text{T}}{\bm{T}}({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}})-{A}(\bm{\eta}({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}))}\right\},
equation (12.10) (12.10)
p^(𝒚|𝒙;𝜽)\displaystyle{\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};% \bm{\theta}}\right)}
=g⁢(𝒚)⁢exp⁡{(𝒃y^+𝐖y^⁢x^T⁢𝑻⁢(𝒙))T⁢𝑼⁢(𝒚)−B⁢(𝜻⁢(𝒙))}.\displaystyle{}=g({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{% rgb}{.75,0,.25}\bm{y}})\exp\mathopen{}\mathclose{{}\left\{\mathopen{}% \mathclose{{}\left(\bm{b}_{\hat{y}}+\mathbf{W}_{\hat{y}\hat{x}}^{\text{T}}{\bm% {T}}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25% }\bm{x}})}\right)^{\text{T}}{\bm{U}}({\color[rgb]{.75,0,.25}\definecolor[named% ]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}})-{B}(\bm{\zeta}({\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}))}\right\}.

In this case, the joint distribution will take the form of a Boltzmann distribution, Eq. 12.6, with energy77 7 The negative energy was originally referred to as the “harmony” [68]—hence the name “harmonium”—and omitting the negative sign does indeed frequently make the formulae prettier. But the base measure has already spoken for hh, as entropy has for HH—the capital η\eta being indistinguishable from a capital hh. So we work with energy, U^\hat{U}, instead.

equation (12.11) (12.11)
U^⁢(𝒙,𝒚,𝜽)=−𝒃y^T⁢𝑼⁢(𝒚)−𝒃x^T⁢𝑻⁢(𝒙)−𝑼⁢(𝒚)T⁢𝐖y^⁢x^T⁢𝑻⁢(𝒙)−log⁡(h⁢(𝒙)⁢g⁢(𝒚)).\hat{U}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named% ]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{},{\color[rgb]{.75,0,.25}\definecolor% [named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{},\bm{\theta}}\right)=-\bm{b}_{% \hat{y}}^{\text{T}}{\bm{U}}({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}})-\bm{b}_{\hat{x}}^{\text{T}}{\bm{T}}({% \color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x% }})-{\bm{U}}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{y}})^{\text{T}}\mathbf{W}_{\hat{y}\hat{x}}^{\text{T}}{\bm{T}}({% \color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x% }})-\log\mathopen{}\mathclose{{}\left(h({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}})g({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}})}\right).

The parameter gradients are therefore just the elegant

d⁢U^d⁢𝐖y^⁢x^=−𝑻⁢𝑼Td⁢U^d⁢𝒃x^=−𝑻d⁢U^d⁢𝒃y^T=−𝑼T.{\frac{\mathrm{d}{\hat{U}}}{\mathrm{d}{\mathbf{W}_{\hat{y}\hat{x}}}}}=-{\bm{T}% }{\bm{U}}^{\text{T}}\hskip 36.135pt{\frac{\mathrm{d}{\hat{U}}}{\mathrm{d}{\bm{% b}_{\hat{x}}}}}=-{\bm{T}}\hskip 36.135pt{\frac{\mathrm{d}{\hat{U}}}{\mathrm{d}% {\bm{b}_{\hat{y}}^{\text{T}}}}}=-{\bm{U}}^{\text{T}}.

(See Section B.1 in the appendices for a refresher on derivatives with respect to matrices. For brevity, from here on, we omit the arguments of the sufficient statistics.) Substituting these energy gradients into the gradient of the loss function (Eqs. 12.7 and 12.8) yields

equation (12.12) (12.12)
d⁢DKL⁡{p⁢(𝒀)∥p^⁢(𝒀;𝜽)}d⁢𝐖y^⁢x^=𝔼𝑿^,𝒀^⁢[𝑻⁢𝑼T]−𝔼𝑿^,𝒀⁢[𝑻⁢𝑼T]d⁢DKL⁡{p⁢(𝒀)∥p^⁢(𝒀;𝜽)}d⁢𝒃x^=𝔼𝑿^,𝒀^⁢[𝑻]−𝔼𝑿^,𝒀⁢[𝑻]d⁢DKL⁡{p⁢(𝒀)∥p^⁢(𝒀;𝜽)}d⁢𝒃y^T=𝔼𝑿^,𝒀^⁢[𝑼T]−𝔼𝑿^,𝒀⁢[𝑼T].\begin{split}{\frac{\mathrm{d}{\operatorname*{\text{D}_{\text{KL}}}\mathopen{}% \mathclose{{}\left\{{p\mathopen{}\mathclose{{}\left({\bm{Y}}}\right)}\middle\|% {\hat{p}\mathopen{}\mathclose{{}\left({\bm{Y}};\bm{\theta}}\right)}}\right\}}}% {\mathrm{d}{\mathbf{W}_{\hat{y}\hat{x}}}}}&{}=\mathbb{E}_{{\bm{\hat{X}}}{},{% \bm{\hat{Y}}}{}}{\mathopen{}\mathclose{{}\left[{\bm{T}}{\bm{U}}^{\text{T}}}% \right]}-\mathbb{E}_{{\bm{\hat{X}}}{},{\bm{Y}}{}}{\mathopen{}\mathclose{{}% \left[{\bm{T}}{\bm{U}}^{\text{T}}}\right]}\\ {\frac{\mathrm{d}{\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}% \left\{{p\mathopen{}\mathclose{{}\left({\bm{Y}}}\right)}\middle\|{\hat{p}% \mathopen{}\mathclose{{}\left({\bm{Y}};\bm{\theta}}\right)}}\right\}}}{\mathrm% {d}{\bm{b}_{\hat{x}}}}}&{}=\mathbb{E}_{{\bm{\hat{X}}}{},{\bm{\hat{Y}}}{}}{% \mathopen{}\mathclose{{}\left[{\bm{T}}}\right]}-\mathbb{E}_{{\bm{\hat{X}}}{},{% \bm{Y}}{}}{\mathopen{}\mathclose{{}\left[{\bm{T}}}\right]}\\ {\frac{\mathrm{d}{\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}% \left\{{p\mathopen{}\mathclose{{}\left({\bm{Y}}}\right)}\middle\|{\hat{p}% \mathopen{}\mathclose{{}\left({\bm{Y}};\bm{\theta}}\right)}}\right\}}}{\mathrm% {d}{\bm{b}_{\hat{y}}^{\text{T}}}}}&{}=\mathbb{E}_{{\bm{\hat{X}}}{},{\bm{\hat{Y% }}}{}}{\mathopen{}\mathclose{{}\left[{\bm{U}}^{\text{T}}}\right]}-\mathbb{E}_{% {\bm{\hat{X}}}{},{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[{\bm{U}}^{\text{T}}% }\right]}.\end{split}

Evidently, learning is complete when the expected sufficient statistics of the model and data (or, more precisely, the model and the hybrid joint distribution) match. Nevertheless, the unfortunate expectation under the model shows up in these equations (except the last, since 𝑼{\bm{U}} is a function only of 𝒀{\bm{Y}}).

On the other hand, the structure of the harmonium does make possible block Gibbs sampling, i.e. initializing 𝒚^\bm{\hat{y}} randomly and then repeatedly sampling from Eq. 12.9 and then from Eq. 12.10. A single step of block Gibbs sampling (i.e., sampling both 𝒙^\bm{\hat{x}} and 𝒚^\bm{\hat{y}}) can be used as the transition operator for Markov chain, which will eventually generated samples from the model distribution.

Contrastive divergence for EFHs.

Alternatively, we can use the method of contrastive divergence described in Section 12.1.2. Analogous to Eq. 12.3, this yields the following updates for the EFH:

equation (12.13) (12.13)
Δ⁢𝜽∝set−⟨∂U^∂𝜽⁢(𝑿^0,𝒀0,𝜽)−⟨∂U^∂𝜽⁢(𝑿^n,𝒀^n,𝜽)⟩𝑿^n,𝒀^n⟩𝑿^0,𝒀0.\Delta\bm{\theta}\stackrel{{\scriptstyle\text{set}}}{{\propto}}-{\mathopen{}% \mathclose{{}\left\langle{\frac{\partial{\hat{U}}}{\partial{{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\theta}}}}% \mathopen{}\mathclose{{}\left({\bm{\hat{X}}}^{0},{\bm{Y}}^{0},\bm{\theta}}% \right)-{\mathopen{}\mathclose{{}\left\langle{\frac{\partial{\hat{U}}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{\theta}}}}\mathopen{}\mathclose{{}\left({\bm{\hat{X}}}^{n},{\bm{% \hat{Y}}}^{n},\bm{\theta}}\right)}}\right\rangle_{{\bm{\hat{X}}}^{n}{},{\bm{% \hat{Y}}}^{n}{}}}}}\right\rangle_{{\bm{\hat{X}}}^{0}{},{\bm{Y}}^{0}{}}}.

Here I use the same notation as in Section 12.1.2, with superscripts indicating the number of steps taken down the Markov chain. Note that 𝑿^0{\bm{\hat{X}}}^{0} is therefore distributed according to ⟨p∞(𝒙|𝒀0;𝜽)⟩𝒀0{\mathopen{}\mathclose{{}\left\langle{{p^{\infty}\mathopen{}\mathclose{{}\left% ({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm% {x}}{}\middle|{\bm{Y}}^{0};\bm{\theta}}\right)}}}\right\rangle_{{\bm{Y}}^{0}{}}}; i.e., every 𝒙^0\bm{\hat{x}}^{0} is drawn from the posterior conditioned on an actual datum, 𝒚0\bm{y}^{0}. Like Eq. 12.3, the second average must be nested inside the first.

In order to facilitate a biological interpretation, consider EFHs in which the sufficient statistics are identity functions, 𝑼⁢(𝒚)=𝒚{\bm{U}}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{y}})={\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{% rgb}{.75,0,.25}\bm{y}}, 𝑻⁢(𝒙)=𝒙{\bm{T}}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{x}})={\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{% rgb}{.75,0,.25}\bm{x}}. This is the case, for example, for the RBM. Furthermore, during training, let us take only one step down the Markov chain before taking averages, i.e. CD1. Then the updates become

equation (12.14) (12.14)
Δ⁢𝐖y^⁢x^∝⟨𝑿^0⁢𝒀0T−⟨𝑿^1⁢𝒀^1T⟩𝑿^1,𝒀^1|𝑿^0,𝒀0⟩𝑿^0,𝒀0,Δ⁢𝒃x^∝⟨𝑿^0−⟨𝑿^1⟩𝑿^1|𝑿^0,𝒀0⟩𝑿^0,𝒀0,Δ⁢𝒃y^∝⟨𝒀0−⟨𝒀^1⟩𝒀^1|𝑿^0,𝒀0⟩𝑿^0,𝒀0.\begin{split}\Delta\mathbf{W}_{\hat{y}\hat{x}}&{}\propto{\mathopen{}\mathclose% {{}\left\langle{{{\bm{\hat{X}}}^{0}{{\bm{Y}}^{0}}}^{\text{T}}-{\mathopen{}% \mathclose{{}\left\langle{{{\bm{\hat{X}}}^{1}{{\bm{\hat{Y}}}^{1}}}^{\text{T}}}% }\right\rangle_{{\bm{\hat{X}}}^{1}{},{\bm{\hat{Y}}}^{1}{}|{\bm{\hat{X}}}^{0}{}% ,{\bm{Y}}^{0}{}}}}}\right\rangle_{{\bm{\hat{X}}}^{0}{},{\bm{Y}}^{0}{}}},\\ \Delta\bm{b}_{\hat{x}}&{}\propto{\mathopen{}\mathclose{{}\left\langle{{\bm{% \hat{X}}}^{0}-{\mathopen{}\mathclose{{}\left\langle{{\bm{\hat{X}}}^{1}}}\right% \rangle_{{\bm{\hat{X}}}^{1}{}|{\bm{\hat{X}}}^{0}{},{\bm{Y}}^{0}{}}}}}\right% \rangle_{{\bm{\hat{X}}}^{0}{},{\bm{Y}}^{0}{}}},\\ \Delta\bm{b}_{\hat{y}}&{}\propto{\mathopen{}\mathclose{{}\left\langle{{\bm{Y}}% ^{0}-{\mathopen{}\mathclose{{}\left\langle{{\bm{\hat{Y}}}^{1}}}\right\rangle_{% {\bm{\hat{Y}}}^{1}{}|{\bm{\hat{X}}}^{0}{},{\bm{Y}}^{0}{}}}}}\right\rangle_{{% \bm{\hat{X}}}^{0}{},{\bm{Y}}^{0}{}}}.\end{split}

Thought of as a neural network, we can say that each sample vector drives activity in the layer above, which reciprocally drives activity in the layer below, which drives activity in the layer above; after which “synaptic strengths” change proportional to pairwise correlations (average products) between the pre- and post-synaptic units, with the initial contributions being Hebbian and the final contributions being anti-Hebbian. For CDn, n>1n>1, the reciprocal activity simply continues for longer before synaptic changes are made.

12.2.3 Learning with deep belief networks

We summarize our progress in the previous section in fitting EFHs to data. Since we will shortly need to introduce subscripts to the random variables, we avoid clutter from here on by setting aside contrastive divergence and working out the results in terms of the original loss function (see Eq. 12.2)—allowing us to dispense with superscripts. Here, then, we return to using p^\hat{p} rather than p∞p^{\infty} for the model distribution.

To recapitulate: the EFH represents, in some sense, a generative model more “agnostic” than the directed ones learned with EM: rather than committing to a prior distribution of latent variables, p^⁢(𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}};\bm{\theta}}\right)}, it licenses a certain inference procedure to them, p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}};\bm{\theta}}\right)}. The price we pay for the ease of inference is difficulty in generating samples from, or taking expectations under, the unconditional (joint or marginal) model distributions. Computing the gradients for latent-variable density estimation (Eq. 12.8) requires just such operations, so the price may appear to be steep. However, an alternative procedure which requires very few samples, the method of contrastive divergence (Eq. 12.13), works well in practice. It can be justified either as a crude approximation to the original learning procedure, or as the approximate descent of an objective function slightly different from, but having the same minimum as, the original.

Supposing even that our learning procedure does minimize the relative entropy of the data p⁢(𝒚){p\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}}\right)} and model p^⁢(𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}};\bm{\theta}}\right)} distributions, that divergence may not reach zero. The statistics of the data may be too rich to be representable by an EFH, or (say) one with a given number of hidden units. It would be nice to have a procedure for augmenting this trained EFH that is guaranteed to improve performance, i.e., to decrease relative entropy.

From marginal to joint relative entropy.

In fact, it is possible to provably improve the model (or at least make it no worse) with a simple procedure. The high-level idea is to retain the emission, p^(𝒚0|𝒙0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}\middle|{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}};\bm{% \theta}_{0}}\right)}, from the trained EFH and try to improve (or replace) only the prior, p^⁢(𝒙0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}};\bm{\theta}_{0}}\right)}. Of course, the whole point of the EFH is that the prior is learned only implicitly, so it may seem an infelicitous candidate for replacement. In particular, if we substitute a new prior, p^⁢(𝒙1;𝜽1){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}};\bm{\theta}_{1}}\right)}, we shall seemingly be unable to avail ourselves of the EFH learning procedures—e.g., the contrastive-divergence parameter updates, Eq. 12.13. These rules require the posterior, and although we have one consistent with p^⁢(𝒙0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}};\bm{\theta}_{0}}\right)} and p^(𝒚0|𝒙0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}\middle|{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}};\bm{% \theta}_{0}}\right)}, to wit p^(𝒙0|𝒚0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}}\middle|{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};\bm{% \theta}_{0}}\right)}, we do not have in hand one consistent with p^⁢(𝒙1;𝜽1){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}};\bm{\theta}_{1}}\right)} and p^(𝒚0|𝒙0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}\middle|{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}};\bm{% \theta}_{0}}\right)}—call it p^(𝒙1|𝒚0;𝜽0,𝜽1){\ignorespaces\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};% \bm{\theta}_{0},\bm{\theta}_{1}}\right)}. Nor is it clear how we should get one (although the reader is invited to think about this).

So we turn for inspiration to expectation-maximization (EM), the learning procedure for directed graphical models, which is in some sense what our problem has become, since we now have a parameterized emission, p^(𝒚0|𝒙0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}\middle|{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}};\bm{% \theta}_{0}}\right)}, and prior, p^⁢(𝒙1;𝜽1){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}};\bm{\theta}_{1}}\right)}, even if the latter has yet to be specified. Recall from Section 8.3 that our problem may be simplified if we trade descent in the marginal relative entropy of the data and model distributions for descent in an upper bound, the joint relative entropy. The slack in the bound is taken up by the relative entropy of a “recognition model,” i.e. another posterior distribution, and the posterior implied by the generative model (recall Eq. 8.6). In the present case, let us select the original EFH’s posterior, p^(𝒙0|𝒚0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}}\middle|{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};\bm{% \theta}_{0}}\right)}, as the recognition distribution. As we have lately noted, abandoning this model’s prior presumably spoils the validity of its posterior in the augmented model—that is, in general, p^(𝒙|𝒚0;𝜽0,𝜽1)≠p^(𝒙|𝒚0;𝜽0){\ignorespaces\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}\middle|{\color[rgb]% {.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};\bm{% \theta}_{0},\bm{\theta}_{1}}\right)}\neq{\hat{p}\mathopen{}\mathclose{{}\left(% {\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{% x}}\middle|{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{y}_{0}};\bm{\theta}_{0}}\right)}. To emphasize that the right-hand side of the inequality (the original posterior) is a proxy for the left-hand side, we will subsequently refer to it as pˇ(𝒙1|𝒚0;𝜽0){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{\ignorespaces 1}}\middle|{\color% [rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}% ;\bm{\theta}_{0}}\right)}, and its “aggregated” form as

equation (12.15) (12.15)
pˇ(𝒙1;𝜽0) . . =∑𝒚0pˇ(𝒙1|𝒚0;𝜽0)p(𝒚0).{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{\ignorespaces 1}};\bm{\theta}_{0% }}\right)}\mathrel{\vbox{\hbox{.}\hbox{.} }}=\sum_{\bm{y}_{0}{}}{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{% \ignorespaces 1}}\middle|\bm{y}_{0};\bm{\theta}_{0}}\right)}{p\mathopen{}% \mathclose{{}\left(\bm{y}_{0}}\right)}.

With these definitions in hand, the joint relative entropy can be written (cf. Eq. 8.6) as

equation (12.16) (12.16)
ℒ︀JRE⁢({𝜽0,𝜽1},𝜽0)=DKL{pˇ(𝑿ˇ1|𝒀0;𝜽0)p(𝒀0)∥p^(𝒀0|𝑿ˇ1;𝜽0)p^(𝑿ˇ1;𝜽1)}=DKL{p(𝒀0)∥p^(𝒀0;𝜽0)}+DKL{pˇ(𝑿ˇ1|𝒀0;𝜽0)∥p^(𝑿ˇ1|𝒀0;𝜽0,𝜽1)}=+DKL⁡{pˇ⁢(𝑿ˇ1;𝜽0)∥p^⁢(𝑿ˇ1;𝜽1)}.\begin{split}\mathcal{L}_{\text{JRE}}(\{\bm{\theta}_{0},\bm{\theta}_{1}\},\bm{% \theta}_{0})&{}=\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}% \left\{{\check{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}_{1}\middle|{% \bm{Y}}_{0};\bm{\theta}_{0}}\right)}{p\mathopen{}\mathclose{{}\left({\bm{Y}}_{% 0}}\right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{Y}}_{0}\middle|% {\bm{\check{X}}}_{1};\bm{\theta}_{0}}\right)}{\hat{p}\mathopen{}\mathclose{{}% \left({\bm{\check{X}}}_{1};\bm{\theta}_{1}}\right)}}\right\}\\ &{}=\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{p% \mathopen{}\mathclose{{}\left({\bm{Y}}_{0}}\right)}\middle\|{\hat{p}\mathopen{% }\mathclose{{}\left({\bm{Y}}_{0};\bm{\theta}_{0}}\right)}}\right\}+% \operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{X}}}_{1}\middle|{\bm{Y}}_{0};\bm{% \theta}_{0}}\right)}\middle\|{\ignorespaces\hat{p}\mathopen{}\mathclose{{}% \left({\bm{\check{X}}}_{1}\middle|{\bm{Y}}_{0};\bm{\theta}_{0},\bm{\theta}_{1}% }\right)}}\right\}\\ &{}\stackrel{{\scriptstyle\text{+}}}{{=}}\operatorname*{\text{D}_{\text{KL}}}% \mathopen{}\mathclose{{}\left\{{\check{p}\mathopen{}\mathclose{{}\left({\bm{% \check{X}}}_{1};\bm{\theta}_{0}}\right)}\middle\|{\hat{p}\mathopen{}\mathclose% {{}\left({\bm{\check{X}}}_{1};\bm{\theta}_{1}}\right)}}\right\}.\end{split}

The final line††margin: Exercise LABEL:ex: reminds us that we are proposing to optimize only the parameters 𝜽1\bm{\theta}_{1} of the new prior, so most of the joint relative entropy is irrelevant. Does this help?

Unrolling the EFH.

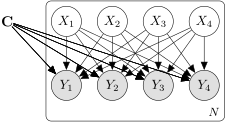
Now we make a very clever observation [25]. Consider the “hybrid” graphical model in Fig. 12.1b.††margin: Insert figure of (a) EFH, and (b) inverted EFH with one directed connection “hanging” off. Samples from this model can be generated by, first, prolonged Gibbs sampling from the “inverted” EFH (notice the labels), followed by a single sample from the bottommost layer via the directed connections. But if the weight matrix defining these connections is the transpose of the EFH’s weight matrix, then samples from this model are identical to samples from the visible layer of a standard EFH, Fig. 12.1a! Likewise, the recognition distributions from the models in Fig. 12.1a,12.1b, pˇ(𝒙1|𝒚0;𝜽0){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{\ignorespaces 1}}\middle|{\color% [rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}% ;\bm{\theta}_{0}}\right)} and p^(𝒙1|𝒚0;𝜽0,𝜽0){\ignorespaces\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};% \bm{\theta}_{0},\bm{\theta}_{0}}\right)}, are identical.

a
b
c
Figure 12.1: Different views of the exponential family harmonium. (12.1a) An EFH. (12.1b) An EFH with one layer “unrolled.” As long as the 𝐖1=𝐖2T\mathbf{W}_{1}=\mathbf{W}_{2}^{\text{T}}, this is equivalent to (12.1a). (12.1c) An EFH with two layers “unrolled.”

Suppose then we let the prior over 𝑿^1{\bm{\hat{X}}}_{1} in the model we seek to learn, p^⁢(𝒙1;𝜽1){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}};\bm{\theta}_{1}}\right)}, be the marginal distribution over 𝑿^1{\bm{\hat{X}}}_{1} in a second, inverted EFH, as in Fig. 12.1b. Moreover, let us initialize the parameters of this EFH at those of the first, fully trained EFH: 𝜽1=set𝜽0\bm{\theta}_{1}\stackrel{{\scriptstyle\text{set}}}{{=}}\bm{\theta}_{0}. At this point in training, the posterior relative entropy on the second line in Eq. 12.16 is zero, so following the gradient of Eq. 12.16 decreases—at least at first—the relative entropy of interest.

This closely resembles the M step of EM with invertible generative models, and the logic of the bound is the same. As soon as 𝜽1\bm{\theta}_{1} is changed, the bound on the marginal relative entropy (MRE) can loosen, because the posterior relative entropy (PRE) can increase (but never decrease below zero). But so far from being problematic, decreases in the joint relative entropy (JRE) that loosen the bound correspond to even greater decreases in the MRE. That is, if the PRE grows, it does so at the expense of the MRE; and if it doesn’t (i.e., it stays at zero), then the MRE still decreases. It is true that subsequent movement along this gradient can decrease the PRE, and therefore allow the MRE to increase, all while lowering the JRE. But the MRE can never increase past its value at the beginning of the changes of 𝜽1\bm{\theta}_{1}, since here the bound is tight, and all changes lower this bound. In fine, the network with a “rolled out” directed layer can never be worse (have higher MRE) than its point of departure, the original EFH of Fig. 12.1a. This is shown graphically in Fig. LABEL:fig:DBNupperbound.††margin: Insert schematic plot of JRE upper bounding MRE.

So much for the M step. However, there is no subsequent E step because there is no obvious way to bring the recognition model, pˇ(𝒙1|𝒚0;𝜽0){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{\ignorespaces 1}}\middle|{\color% [rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}% ;\bm{\theta}_{0}}\right)}, back into agreement with the generative-model posterior, p^(𝒙1|𝒚0;𝜽0,𝜽1){\ignorespaces\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};% \bm{\theta}_{0},\bm{\theta}_{1}}\right)}. We shall employ instead a different iterative improvement scheme, consisting in some sense of a series of M steps.

Recursive application of the procedure.

The second stage of training just described amounts to training a second EFH—albeit on the empirical data as transformed by the first EFH’s recognition model, Eq. 12.15, rather than the data in their raw form.88 8 In practice, means rather than samples from the recognition model are frequently used for training the second EFH. Eq. 12.16 shows that this can likewise be written as minimizing a (marginal) relative entropy. This observation suggests, what is true, that the entire procedure can be applied recursively. After training the second (inverted) EFH, the MRE in Eq. 12.16 may not be zero. Then a second directed layer can be “unrolled” from the EFH spool (Fig. 12.1c), and trained on a new “data distribution,” consisting of the “data distribution,” pˇ⁢(𝒙1;𝜽0){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{\ignorespaces 1}};\bm{\theta}_{0% }}\right)}, used to train its predecessor, transformed by its predecessor’s recognition model, pˇ(𝒚2|𝒙1;𝜽1){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{\ignorespaces 2}}\middle|{\color% [rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}}% ;\bm{\theta}_{1}}\right)}, to wit ∑𝒙ˇ1pˇ(𝒚2|𝒙ˇ1;𝜽1)pˇ(𝒙ˇ1;𝜽0)= . . pˇ(𝒚2;𝜽0,𝜽1)\sum_{\bm{\check{x}}_{1}{}}{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb% ]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{% \ignorespaces 2}}\middle|\bm{\check{x}}_{1};\bm{\theta}_{1}}\right)}{\check{p}% \mathopen{}\mathclose{{}\left(\bm{\check{x}}_{1};\bm{\theta}_{0}}\right)}=% \mathrel{\vbox{\hbox{.}\hbox{.} }}{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{\ignorespaces 2}};\bm{\theta}_{0% },\bm{\theta}_{1}}\right)}.

Can we guarantee that this will continue to decrease (or at least not increase) the model fit to the observed data? In fact we cannot, but we can guarantee something nearly as good: Either the model fits the data better, i.e. we reduce DKL⁡{p⁢(𝒀0)∥p^⁢(𝒀0;𝜽0,𝜽1,𝜽2)}\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{p\mathopen% {}\mathclose{{}\left({\bm{Y}}_{0}}\right)}\middle\|{\hat{p}\mathopen{}% \mathclose{{}\left({\bm{Y}}_{0};\bm{\theta}_{0},\bm{\theta}_{1},\bm{\theta}_{2% }}\right)}}\right\}; or the generative-model posteriors get closer to the recognition models. And this guarantee extends to deeper layers. In short, under this greedy, layer-wise training, either the resulting “deep belief network” becomes a better generative model, or it becomes a better recognition model.

To see this, we apply the argument, given in the previous section for the first “unrolled” EFH, to a second. ††margin: Put in some figures for this!! Maybe you can use previous figs, but you should also have a (c) with three sets of parameters, so four layers. Decoupling 𝜽2\bm{\theta}_{2} from 𝜽1\bm{\theta}_{1} and descending the gradient of

DKL⁡{pˇ⁢(𝒀ˇ2;𝜽0,𝜽1)∥p^⁢(𝒀ˇ2;𝜽2)}\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{Y}}}_{2};\bm{\theta}_{0},\bm{\theta}% _{1}}\right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{Y}}}_{% 2};\bm{\theta}_{2}}\right)}}\right\}

(that is, improving the prior over 𝒀^2{\bm{\hat{Y}}}_{2}) will at least initially decrease

DKL⁡{pˇ⁢(𝑿ˇ1;𝜽0)∥p^⁢(𝑿ˇ1;𝜽1,𝜽2)},\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{X}}}_{1};\bm{\theta}_{0}}\right)}% \middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}_{1};\bm{\theta% }_{1},\bm{\theta}_{2}}\right)}}\right\},

by way of decreasing a JRE upper bound that is initially tight (analogous to Eq. 12.16). Now, p^⁢(𝒙1;𝜽1,𝜽2){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}};\bm{\theta}_{1},\bm{\theta}_% {2}}\right)} is likewise a prior over the subsequent layer, 𝒀^0{\bm{\hat{Y}}}_{0}, so decreasing this marginal relative entropy decreases a second JRE upper bound (Eq. 12.16), albeit in this case not one that is initially tight. Therefore, decreasing this MRE either decreases the MRE of the next layer,

DKL⁡{p⁢(𝒀0)∥p^⁢(𝒀0;𝜽0,𝜽1,𝜽2)},\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{p\mathopen% {}\mathclose{{}\left({\bm{Y}}_{0}}\right)}\middle\|{\hat{p}\mathopen{}% \mathclose{{}\left({\bm{Y}}_{0};\bm{\theta}_{0},\bm{\theta}_{1},\bm{\theta}_{2% }}\right)}}\right\},

or it renders this level’s posterior distribution, p^(𝒙1|𝒚0;𝜽0,𝜽1,𝜽2){\ignorespaces\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};% \bm{\theta}_{0},\bm{\theta}_{1},\bm{\theta}_{2}}\right)}, a better match to the recognition model, pˇ(𝒙1|𝒚0;𝜽0){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{\ignorespaces 1}}\middle|{\color% [rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}}% ;\bm{\theta}_{0}}\right)}. And note that this last MRE is the one we actually care about: the deep belief network’s fit to the observed data.

After the initial improvement of the prior over 𝒀^2{\bm{\hat{Y}}}_{2}, the first JRE bound can loosen, after which not all improvements in this prior translate into improvements in the prior over 𝑿^1{\bm{\hat{X}}}_{1}. But (1) any other improvement comes from making p^(𝒚2|𝒙1;𝜽1,𝜽2){\ignorespaces\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{2}}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}};% \bm{\theta}_{1},\bm{\theta}_{2}}\right)} more consistent with pˇ(𝒚2|𝒙1;𝜽1){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{\ignorespaces 2}}\middle|{\color% [rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}}% ;\bm{\theta}_{1}}\right)}; and (2) the prior over 𝑿^1{\bm{\hat{X}}}_{1}, p^⁢(𝒙1;𝜽1,𝜽2){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{1}};\bm{\theta}_{1},\bm{\theta}_% {2}}\right)}, can never get worse than it was before 𝜽2\bm{\theta}_{2} was decoupled from 𝜽1\bm{\theta}_{1}. Extending the entire argument to deeper belief networks is straightforward.

Picturesquely, we can describe the whole procedure as follows. After training the first EFH, we freeze the way that “first-order features” give rise to data. But we need more flexibility in the prior distribution of first-order features. So we train a new EFH to generate them. Our training procedure makes this second EFH more likely to generate features that either generate good data, 𝒀^{\bm{\hat{Y}}}, or are more consistent with the recognition model being used to extract the “training features.” This is akin to an M step in EM. When this learning process stalls out, we should like to tighten up the bound and begin again, as in the E step of EM, which would require somehow making the recognition distribution more like the posterior under our “hybrid” model. Instead, we simply repeat the procedure of replacing the prior—this time over “second-order features”—with another EFH. Although learning in this third EFH cannot be claimed to tighten the original bound, it does impose a tight bound on this bound: improvement in the generation of second-order features—the hidden variables for the first-order features—is guaranteed to improve first-order features, at least initially. Whether this improvement comes by way of improving data generation, or merely the bound on it, is not typically obvious.

The procedure is only guaranteed to keep lowering bounds (or bounds on bounds, etc.) if the new EFHs are introduced with their parameters initialized to the previous EFH’s parameter values. In practice, however, this is almost always relaxed, because the new EFH is seldom even chosen to have the appropriate shape (same number of hidden units as the previous EFH’s number of visible units). This allows for very general models; and although not guaranteed to keep improving performance, the introduction of deeper EFHs can be roughly justified along similar lines: it allows for more flexible priors over increasingly complex features.

Summary.

We summarize the entire procedure for training deep belief networks with a pair of somewhat hairy definitions and a pair of learning rules. Writing in terms of pairs is required simply to maintain a connection to the notational distinction between latent and observed variables in the original EFH; conceptually, the training is the same at every layer.

pˇ⁢(𝒚m;𝜽0,…,𝜽m−1)\displaystyle{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{m}};\bm{\theta}_{0}% ,\ldots,\bm{\theta}_{m-1}}\right)}
. . =∑𝒙ˇm−1pˇ(𝒚m|𝒙ˇm−1;𝜽m−1)pˇ(𝒙ˇm−1;𝜽0,…,𝜽m−2)\displaystyle{}\mathrel{\vbox{\hbox{.}\hbox{.} }}=\sum_{\bm{\check{x}}_{m-1}{}}{\check{p}\mathopen{}\mathclose{{}\left({% \color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y% }_{m}}\middle|\bm{\check{x}}_{m-1};\bm{\theta}_{m-1}}\right)}{\check{p}% \mathopen{}\mathclose{{}\left(\bm{\check{x}}_{m-1};\bm{\theta}_{0},\ldots,\bm{% \theta}_{m-2}}\right)}
for m≥1m\geq 1 even
pˇ⁢(𝒙m;𝜽0,…,𝜽m−1)\displaystyle{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{m}};\bm{\theta}_{0}% ,\ldots,\bm{\theta}_{m-1}}\right)}
. . =∑𝒚ˇm−1pˇ(𝒙m|𝒚ˇm−1;𝜽m−1)pˇ(𝒚ˇm−1;𝜽0,…,𝜽m−2)\displaystyle{}\mathrel{\vbox{\hbox{.}\hbox{.} }}=\sum_{\bm{\check{y}}_{m-1}{}}{\check{p}\mathopen{}\mathclose{{}\left({% \color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x% }_{m}}\middle|\bm{\check{y}}_{m-1};\bm{\theta}_{m-1}}\right)}{\check{p}% \mathopen{}\mathclose{{}\left(\bm{\check{y}}_{m-1};\bm{\theta}_{0},\ldots,\bm{% \theta}_{m-2}}\right)}
for m≥1m\geq 1 odd.

Then:

Δ⁢𝜽m\displaystyle\Delta\bm{\theta}_{m}
∝−dd⁢𝜽m⁢DKL⁡{pˇ⁢(𝒀ˇm;𝜽0,…,𝜽m−1)∥p^⁢(𝒀ˇm;𝜽m)}\displaystyle{}\propto-{\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}_{m}}}}% \operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{Y}}}_{m};\bm{\theta}_{0},\ldots,\bm{% \theta}_{m-1}}\right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{% \check{Y}}}_{m};\bm{\theta}_{m}}\right)}}\right\}
for m≥1m\geq 1 even
equation (12.18) (12.18)
Δ⁢𝜽m\displaystyle\Delta\bm{\theta}_{m}
∝−dd⁢𝜽m⁢DKL⁡{pˇ⁢(𝑿ˇm;𝜽0,…,𝜽m−1)∥p^⁢(𝑿ˇm;𝜽m)}\displaystyle{}\propto-{\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}_{m}}}}% \operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{X}}}_{m};\bm{\theta}_{0},\ldots,\bm{% \theta}_{m-1}}\right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{% \check{X}}}_{m};\bm{\theta}_{m}}\right)}}\right\}
for m≥1 odd.\displaystyle\text{for $m\geq 1$ odd}.

Failure modes.

For an EFH to match the data distribution, its prior distribution (over 𝑿^{\bm{\hat{X}}}) must match the “aggregrated” posterior:

pˇ⁢(𝒙1;𝜽0)=∑𝒚0pˇ(𝒙1|𝒚0;𝜽0)p(𝒚0)p^⁢(𝒚0;𝜽0)=setp⁢(𝒚0)⟹=∑𝒚0p^(𝒙0|𝒚0;𝜽0)p^(𝒚0;𝜽0)=p^(𝒙0;𝜽0).\begin{split}{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{\ignorespaces 1}};% \bm{\theta}_{0}}\right)}&{}=\sum_{\bm{y}_{0}{}}{\check{p}\mathopen{}\mathclose% {{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{x}_{\ignorespaces 1}}\middle|\bm{y}_{0};\bm{\theta}_{0}}\right)}% {p\mathopen{}\mathclose{{}\left(\bm{y}_{0}}\right)}\\ {\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};\bm{\theta}_{0}}\right)}% \stackrel{{\scriptstyle\text{set}}}{{=}}{p\mathopen{}\mathclose{{}\left({% \color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y% }_{0}}}\right)}\implies&{}=\sum_{\bm{y}_{0}{}}{\hat{p}\mathopen{}\mathclose{{}% \left({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{x}_{0}}\middle|\bm{y}_{0};\bm{\theta}_{0}}\right)}{\hat{p}% \mathopen{}\mathclose{{}\left(\bm{y}_{0};\bm{\theta}_{0}}\right)}={\hat{p}% \mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}};\bm{\theta}_{0}}\right)}.\end{split}

However, the converse is not true, since the match of prior and aggregated posterior only requires that

∑𝒚0[p(𝒚0)−p^(𝒚0;𝜽0)]p^(𝒙0|𝒚0;𝜽0)=0,\sum_{\bm{y}_{0}{}}\mathopen{}\mathclose{{}\left[{p\mathopen{}\mathclose{{}% \left(\bm{y}_{0}}\right)}-{\hat{p}\mathopen{}\mathclose{{}\left(\bm{y}_{0};\bm% {\theta}_{0}}\right)}}\right]{\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb% ]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}_{0}}% \middle|\bm{y}_{0};\bm{\theta}_{0}}\right)}=0,

which does not imply a unique solution for p^⁢(𝒚0;𝜽0){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}_{0}};\bm{\theta}_{0}}\right)}. Now suppose that after training, the first EFH in a DBN satisfies this equation. Then the second EFH, trained on its aggregated posterior, will learn only to match the first EFH—indeed, if it is initialized at 𝜽1=set𝜽0\bm{\theta}_{1}\stackrel{{\scriptstyle\text{set}}}{{=}}\bm{\theta}_{0}, then the loss will start at a global minimum and the second EFH will not be updated at all. This occurs even if the first EFH did not match the data distribution. So the addition of more layers in this case will not improve the model fit.

††margin: Goodfellow’s critique; notes on the assumption of a factorial posterior; complementary priors; etc.