4.2 The exponential-family harmonium
In Chapter 3, we encountered a direct trade-off between the expressivity of the model emission distribution, , and the model posterior, , imposed by Bayes’s theorem. In particular, applying Bayes’s theorem requires integrating the product of the emission and prior () densities across all configurations of the latent variables, . For continuous-valued , this integral is tractable only for specially selected prior and emission densities. For discrete-valued , the integral becomes a sum, which is only computationally feasible for low-dimensional : the number of summands is exponential in .
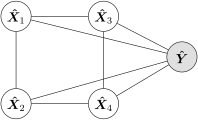
In this section, we discuss a model in which inference is trivial, although at the cost that it is the joint and marginal distributions that are computable only up to the normalizer. We derive the model in two ways: first (Section 4.2.1), the classical one which begins with a certain undirected graph (Fig. 4.2) and proceeds to show how this makes inference trivial; and second (Section 4.2.2), a more general approach, that starts with exponential-family emission and posterior, and shows under what (more general) conditions they are compatible with each other.
4.2.1 Derivation of the EFH
Consider the undirected graphical model in Fig. 4.2. Its principal feature is the lack of edges between latent variables and (likewise) the lack of edges between observed variables.11 1 Historically for the RBM, these were typically called the hidden and visible units, respectively, and we use this convention in what follows. These restrictions cause both the emission and posterior to factor completely, which can be seen by (e.g.) applying the Bayes-ball algorithm to Fig. 4.2 with (respectively) the hidden or the visible variables shaded. This will certainly simplify inference, but there is a price to paid—we discuss this below.
The joint distribution.
The joint distribution for undirected graphical models is the (normalized) product over all maximal cliques of the graph, which in this case are all the (hidden, visible) pairs. To make any progress beyond this, we impose an additional constraint, namely that the clique energies are bilinear in (some functions of) and . I will write this bilinear function in a particular form that stays completely general but facilitates the interpretations we make next:
There are a few important things to note about this formulation. First, it clearly contains redundancies, at least under the assumption that the component functions are arbitrary. For example, the second and third terms are redundant with the final two. (Note that we are assuming and to be strictly positive.) The weight likewise adds no expressive power. However, below we remove these redundancies by committing to a particular form for the functions, but letting the parameters , , and be free (learnable).
Second, the bilinear form greatly restricts the set of energies expressible by the model. However, the EFH need not be restricted this way: The functions and could be replaced with vector-valued functions, and the first term of the energy with their dot product, in which case the set of energies is essentially unlimited (for long enough vectors). In fact, an obvious EFH can be written in this form, as we will see below. But since we will anyway derive a more generic model in the next section, we do not consider this generalization here.
The marginal and conditional distributions.
Now, the marginal distribution over (e.g.) the visible units is
(For discrete , replace the integral with a sum.) To simplify this expression, let us introduce the definitions
under which the marginal becomes
It is now possible to compute the posterior as the ratio of the joint (Eq. 4.1) to this marginal (Eq. 4.3):
Thus, the posterior takes the form of an exponential family. Now we see that our symbol choices for the functions introduced in the definitions Eq. 4.2 were felicitous, since they are precisely the natural parameters and the log-partition function. Notice that this is not merely a case of showing up in the right place in Eq. 4.4; according to our definition in Eq. 4.2, is precisely the log-partition function for this posterior distribution.
A similar progression yields the emission distribution. In particular, if we define
then we obtain
and
The foregoing derivation may look like mere algebraic legerdemain; it is important to see what we have and haven’t accomplished. The conditional distributions, Eqs. 4.4 and 4.7, still contain (log) normalizers which have not been computed explicitly. For generic functions , there is no guarantee that the integral in Eq. 4.2 (or a sum over discrete configurations) is tractable. On the other hand, our notatation suggests, what is true, that for simple functions (e.g., low-order polynomials), the integral (or sum) is not only tractable but known, corresponding to the partition function of some exponential-family distribution or other.
Example: the RBM.
Let us consider the special case in which the random variables are supported on the set . Up to reparameterization, this is the standard Bernoulli distribution. Under the standard parameterization, the sufficient statistics are each the identity function, , ; and the base measures are unity, . Therefore the joint distribution is
4.2.2 Generalized EFHs
Derivation.
In the previous section, we assumed a certain graphical model (Fig. 4.2), with a restriction on the form of the clique potentials, and derived as a consequence that the posterior and emission are exponential-family distributions. We now rederive EFHs from the other direction, starting with exponential-family emission and posterior, and working backwards to derive the joint distribution. We therefore define the emission and posterior to be
(Cf. Eqs. 4.4 and 4.7.) Note that these need not be the same exponential family; indeed, the several elements of (e.g.) need not even belong to the same one.
Now, the ratio of the conditionals is also the ratio of the marginals,
Therefore, it must factor entirely into pieces that refer to at most one of or . The ratio contains only such factors, but the exponential term does not. This term will factor correctly if and only if
for some functions and . It is easily verified that to satisfy Eq. 4.9, it is sufficient (although not strictly necessary) for the natural parameters to take the form
with a shared, albeit transposed, linear transformation . In this case, the marginal distributions become (up to the proportionality constants)
and the conditional distributions become
Multiplying a conditional by the appropriate marginal yields the joint distribution:
The resulting joint distribution (Eq. 4.11) certainly looks very similar to our previous starting point, Eq. 4.1, and it clearly has the same parameter gradient.22 2 We take up the learning problem in Section 12.2. However, there is a subtle difference. We have not assumed the latent variables to be independent conditioned on the observations, or vice versa. That is, we have not assumed the graph of Fig. 4.2. This provides a significant advantage.
Intuitively, good latent variables should be marginally independent, otherwise there is something (their dependence) left to explain; and conditionally dependent, because they should complete to explain the observations. For example, on a page of (handwritten) algebra, the symbols and should be (perhaps) independent—finding a doesn’t change my expectation of finding a . However, for any particular handwritten character on the page, and provide highly dependent (indeed, mutually exclusive) explanations. The traditional EFH cannot model such dependencies, because the posterior is conditionally independent, but the generalized EFH can—e.g., letting the latent vector be a one-hot representation of a categorical random variable, like character ID.
4.2.3 Comparison with directed models
In directed generative models, we have (start with) the emission, , and the prior, , from which we can (typically) easily compute the joint, . For complex likelihoods, the marginal over the observations, , is intractable, and the posterior is computable only up to the normalizer. In the EFH, by contrast, we again have (start with) the emission, , but also the posterior, , rather than the prior. We can compute the joint, the prior, and the marginal only up to a proportionality constant.
Now, in neither the EFH nor complex directed models is the marginal fully available. And losing a closed-form expression for the prior is not per se very limiting. Therefore the major trade-off in the EFH is buying a tractable posterior at the price of a tractable joint. In complex directed models, we cannot take expectations under this joint anyway; but we can easily sample from it, via a so-called ancestral pass; i.e., sampling from the (tractable) prior and thence from the emission. So more to the point, the EFH buys easy inference at the cost of easy generation. Is the trade-off worth it?
-
•
Generation. Generation is not easy, but is it hard? If the conditional distributions in Eq. 4.10 are known exponential families, then samples can be generated with block Gibbs sampling††margin: block Gibbs sampling . That is, one initializes at a random observation vector; draws a sample latent vector from the posterior conditioned on this observation; then draws a sample from the emission conditioned on this latent vector; etc.
Note that conditional independence is not required for block Gibbs sampling. For example, if the latent variables correspond to mutually exclusive categories, then a multinomial sample vector can be drawn with just samples (which can even be drawn in parallel). This will be the preferred method when the number of units is much greater than the number of multinomial trials, , which is a canonical use case, e.g. for sparse coding.33 3 When this condition does not hold, it can be more efficient to expand the posterior via the chain rule of probability and make consecutive samples, i.e. to give up on block Gibbs sampling.
-
•
Inference. Inference is easy, but at what cost? If the conditional distributions are standard exponential families, then the sufficient statistics, and , will be simple functions of their arguments. This in turn limits the complexity of the natural parameters (cf. Eq. 4.10). Alternatively, the sufficient statistics, at least for the emission, can be made arbitrarily complex (e.g., with a neural network), which also makes the posterior a complex function of the observations. But then sampling from the emission distribution will not be easy, and may require iterative procedures, like Langevin dynamics. This is possible and does yield superior models [1], but generation and training will be significantly slower. Still, inference itself will remain fast.
…