5.1 Naïve inference
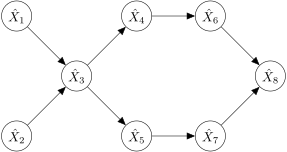
This representation scheme immediately suggests an algorithm for inference—although in fact it is a bad one, as we shall see. Naïvely, we can represent the joint distribution simply as the product of all the conditionals, and then collapse over (marginalize out) all the variables not of interest:
# don't do this: compute the entire joint first
p_X1X2X3X4X5X6X7X8 = (
p_X1*p_X2*p_X3givenX1X2*p_X4givenX3*p_X5givenX3*
p_X6givenX4*p_X7givenX5*p_X8givenX6X7
)
assert p_X1X2X3X4X5X6X7X8.shape == (2, 2, 2, 2, 2, 2, 2, 2)
p_X8 = p_X1X2X3X4X5X6X7X8.sum(axis=(0,1,2,3,4,5,6), keepdims=True)
assert p_X8.shape == (1, 1, 1, 1, 1, 1, 1, 2)
Now think about how many operations were carried out by the single call to sum: In short, numbers (the tabular representation of the joint distribution) were reduced to numbers by addition, so additions were carried out. In general, the costs of such a reduction will be11 1 This cost could surely be called , but for consistency with what follows, we will use the glass-half-full , the reduction across the first axis dominating all subsequent ones. , with the number of states a single discrete random variable can take on, and the number of such variables—in a word, exponentially expensive in the number of variables. In a graph with hundreds of variables, such an approach to inference is infeasible.