10.2 Variational Autoencoders

The use of a recognition distribution for every observation, 𝒚\bm{y}, will clearly fail if the number of data is too large. An alternative is to encourage the recognition model to use a single set of parameters for all data, by specifying a single, parameter-dependent mapping from the observations to the moments of the recognition distribution. For example, sticking with Gaussian recognition distributions, we can use

equation (10.12) (10.12)
pˇ(𝒙|𝒚;ϕ)=𝒩︀(𝝂(𝒚,ϕ𝝂),𝚼(𝒚,ϕ𝚼)).{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\phi}}\right)% }=\mathcal{N}\mathopen{}\mathclose{{}\left({\bm{\nu}({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{},\bm{\phi}_{\bm{% \nu}})},\>{\mathbf{{\Upsilon}}({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}{},\bm{\phi}_{\mathbf{{\Upsilon}}})}}% \right).

The moments, 𝝂⁢(𝒚,ϕ𝝂){\bm{\nu}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{y}}{},\bm{\phi}_{\bm{\nu}})} and 𝚼⁢(𝒚,ϕ𝚼){\mathbf{{\Upsilon}}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor% }{rgb}{.75,0,.25}\bm{y}}{}{},\bm{\phi}_{\mathbf{{\Upsilon}}})}, are now interpreted to be mappings or functions rather than parameters. (It will now be slightly simpler to work with covariance rather than precision matrices.) For example, the functions can be deep neural networks, and so in some sense arbitrarily flexible (see Section 7.1.3). For sufficiently large ϕ\bm{\phi}, this flexibility could include (depending on the ratio of parameters to observations) the ability to store a separate mean and covariance matrix for every datum, and therefore to mimic Eq. 10.2, but ideally it does not. Limiting the flexibility of the functions encourages the computational cost of learning ϕ\bm{\phi} to be “amortized” across observations, and for the recognition model to provide good inferences for new observations 𝒚\bm{y}.

Replacing the moments of the recognition distribution with deep neural networks is the point of departure for ††margin: variational autoencoders [39, 61]. Note well that they are not limited to Gaussian recognition distributions (Eq. 10.12). However, we start with this case because it is a natural extension of the approach to sparse coding just discussed; it will likewise make use of the identities Eqs. 10.3 and 10.4. We subsequently generalize.

The M step.

As usual, the M step amounts to fitting the parameters 𝜽\bm{\theta} of the generative model by minimizing the joint relative entropy. We will not yet impose a generative model, so we write the gradient generically:

equation (10.13) (10.13)
d⁢ℒ︀JREd⁢𝜽=dd⁢𝜽⁢𝔼𝑿ˇ,𝒀⁢[−log⁡p^⁢(𝑿ˇ,𝒀;𝜽)]≈⟨−∂log⁡p^∂𝜽⁢(𝑿ˇ,𝒀;𝜽)⟩𝑿ˇ,𝒀\frac{\mathrm{d}{\mathcal{L}_{\text{JRE}}}}{\mathrm{d}{\bm{\theta}}}=\frac{% \mathrm{d}{}}{\mathrm{d}{\bm{\theta}}}\mathbb{E}_{{\bm{\check{X}}}{},{\bm{Y}}{% }}{\mathopen{}\mathclose{{}\left[-\log{\hat{p}\mathopen{}\mathclose{{}\left({% \bm{\check{X}}},{\bm{Y}};\bm{\theta}}\right)}}\right]}\approx{\mathopen{}% \mathclose{{}\left\langle{-\frac{\partial{\log\hat{p}}}{\partial{{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\theta}}}}% \mathopen{}\mathclose{{}\left({\bm{\check{X}}},{\bm{Y}};\bm{\theta}}\right)}}% \right\rangle_{{\bm{\check{X}}}{},{\bm{Y}}{}}}

This gradient can be descended iteratively.

The E step.

Parameterizing the recognition model with neural networks, rather than fixed parameters (one per observation), only mildly changes the loss gradient. In particular, since the recognition distribution is still normal, we can still use Eq. 10.1 for the joint relative entropy, and Eqs. 10.3 and 10.4 for its gradients. The only addition is the Jacobian of the moment parameters with respect to the neural-network parameters ϕ\bm{\phi}, which accrues via the chain rule of differentiation:

equation (10.14) (10.14)
d⁢ℒ︀JREd⁢ϕ𝝂=𝔼𝒀[∂𝝂T∂ϕ𝝂(𝒀,ϕ𝝂)𝔼𝑿ˇ|𝒀[−∂log⁡p^∂𝒙(𝑿ˇ,𝒀;𝜽)|𝒀]]≈⟨∂𝝂T∂ϕ𝝂⁢(𝒀,ϕ𝝂)⁢⟨−∂log⁡p^∂𝒙⁢(𝑿ˇ,𝒀;𝜽)⟩𝑿ˇ|𝒀⟩𝒀.\begin{split}\frac{\mathrm{d}{\mathcal{L}_{\text{JRE}}}}{\mathrm{d}{\bm{\phi}_% {\bm{\nu}}}}&{}=\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\frac{% \partial{\bm{\nu}}^{\text{T}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\phi}_{\bm{\nu}}}}}\mathopen{}% \mathclose{{}\left({\bm{Y}},\bm{\phi}_{\bm{\nu}}}\right)\mathbb{E}_{{\bm{% \check{X}}}{}|{\bm{Y}}}{\mathopen{}\mathclose{{}\left[-\frac{\partial{\log\hat% {p}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}% {.75,0,.25}{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{x}}}}}\mathopen{}\mathclose{{}\left({\bm{\check{X}}},{\bm{Y}};% \bm{\theta}}\right)\middle|{\bm{Y}}{}}\right]}}\right]}\\ &{}\approx{\mathopen{}\mathclose{{}\left\langle{\frac{\partial{\bm{\nu}}^{% \text{T}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}% {rgb}{.75,0,.25}\bm{\phi}_{\bm{\nu}}}}}\mathopen{}\mathclose{{}\left({\bm{Y}},% \bm{\phi}_{\bm{\nu}}}\right){\mathopen{}\mathclose{{}\left\langle{-\frac{% \partial{\log\hat{p}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}}}}\mathopen{}\mathclose{{}\left({\bm{% \check{X}}},{\bm{Y}};\bm{\theta}}\right)}}\right\rangle_{{\bm{\check{X}}}{}|{% \bm{Y}}{}}}}}\right\rangle_{{\bm{Y}}{}}}.\end{split}

Likewise, for the covariance, we follow Eq. 10.4, although for notational simplicity we write the derivative with respect to only a single parameter, ϕ𝚼i\phi_{\mathbf{{\Upsilon}}}^{i}:

equation (10.15) (10.15)
d⁢ℒ︀JREd⁢ϕ𝚼i=𝔼𝒀[tr[(dd⁢𝚼𝔼𝑿ˇ|𝒀[−logp^(𝑿ˇ,𝒀;𝜽)|𝒀]−12dd⁢𝚼log|𝚼|)∂𝚼∂ϕ𝚼i]]=𝔼𝒀[12tr[(𝔼𝑿ˇ|𝒀[−∂2log⁡p^∂𝒙^⁢∂𝒙^T(𝑿ˇ,𝒀,𝜽)|𝒀]−𝚼−1)∂𝚼∂ϕ𝚼i]]≈⟨12tr[(𝔼𝑿ˇ|𝒀[−∂2log⁡p^∂𝒙^⁢∂𝒙^T(𝑿ˇ,𝒀,𝜽)|𝒀]−𝚼−1)∂𝚼∂ϕ𝚼i]⟩𝒀.\begin{split}\frac{\mathrm{d}{\mathcal{L}_{\text{JRE}}}}{\mathrm{d}{\phi_{% \mathbf{{\Upsilon}}}^{i}}}&{}=\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}% \left[\text{tr}\mathopen{}\mathclose{{}\left[\mathopen{}\mathclose{{}\left(% \frac{\mathrm{d}{}}{\mathrm{d}{\mathbf{{\Upsilon}}}}\mathbb{E}_{{\bm{\check{X}% }}{}|{\bm{Y}}}{\mathopen{}\mathclose{{}\left[-\log{\hat{p}\mathopen{}% \mathclose{{}\left({\bm{\check{X}}},{\bm{Y}};\bm{\theta}}\right)}\middle|{\bm{% Y}}{}}\right]}-\frac{1}{2}\frac{\mathrm{d}{}}{\mathrm{d}{\mathbf{{\Upsilon}}}}% \log\mathopen{}\mathclose{{}\left\lvert\mathbf{{\Upsilon}}}\right\rvert}\right% )\frac{\partial{\mathbf{{\Upsilon}}}}{\partial{{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\phi_{\mathbf{{\Upsilon}}}^% {i}}}}}\right]}\right]}\\ &{}=\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\frac{1}{2}\text{tr}% \mathopen{}\mathclose{{}\left[\mathopen{}\mathclose{{}\left(\mathbb{E}_{{\bm{% \check{X}}}{}|{\bm{Y}}}{\mathopen{}\mathclose{{}\left[-\frac{\partial^{2}{\log% \hat{p}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{% rgb}{.75,0,.25}\bm{\hat{x}}}}\partial{{\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\hat{x}}}}^{\text{T}}}\mathopen{}% \mathclose{{}\left({\bm{\check{X}}},{\bm{Y}},\bm{\theta}}\right)\middle|{\bm{Y% }}{}}\right]}-\mathbf{{\Upsilon}}^{-1}}\right)\frac{\partial{\mathbf{{\Upsilon% }}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\phi_{\mathbf{{\Upsilon}}}^{i}}}}}\right]}\right]}\\ &{}\approx{\mathopen{}\mathclose{{}\left\langle{\frac{1}{2}\text{tr}\mathopen{% }\mathclose{{}\left[\mathopen{}\mathclose{{}\left(\mathbb{E}_{{\bm{\check{X}}}% {}|{\bm{Y}}}{\mathopen{}\mathclose{{}\left[-\frac{\partial^{2}{\log\hat{p}}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{\hat{x}}}}\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{\hat{x}}}}^{\text{T}}}\mathopen{}\mathclose% {{}\left({\bm{\check{X}}},{\bm{Y}},\bm{\theta}}\right)\middle|{\bm{Y}}{}}% \right]}-\mathbf{{\Upsilon}}^{-1}}\right)\frac{\partial{\mathbf{{\Upsilon}}}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\phi_{\mathbf{{\Upsilon}}}^{i}}}}}\right]}}\right\rangle_{{\bm{Y}}{}% }}.\end{split}

(For brevity, some parameter dependence has been suppressed.) Computing the Hessian ∂2U^post/∂𝒙^⁢∂𝒙^T\partial^{2}{\hat{U}_{\text{post}}}/\partial{{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\hat{x}}}}\partial{{% \color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{% \hat{x}}}}^{\text{T}} naïvely is expensive (𝒪︀⁢(K3)\mathcal{O}({K}^{3})) but there are clever, 𝒪︀⁢(K2)\mathcal{O}({K}^{2}), alternatives [61]. For sufficiently expressive generative models, the conditional expectations under the recognition distribution in Eqs. 10.14 and 10.15 will be impossible to carry out (although cf. Eqs. 10.10 and 10.11), so we will typically resort to sample averages. We can then descend these gradients iteratively.

Stochastic backpropagation.

Computing the gradients on the left-hand sides of Eqs. 10.14 and 10.15 evidently requires acquiring the gradients appearing in the right-hand sides. To compute the gradients of the recognition networks, 𝝂⁢(𝒚,ϕ𝝂){\bm{\nu}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{y}}{},\bm{\phi}_{\bm{\nu}})} and 𝚼⁢(𝒚,ϕ𝚼){\mathbf{{\Upsilon}}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor% }{rgb}{.75,0,.25}\bm{y}}{}{},\bm{\phi}_{\mathbf{{\Upsilon}}})}, we can pass observations 𝒚\bm{y} forward through them, and then backpropagate gradient values. To compute the gradient of the generative log probability, log⁡p^⁢(𝒙,𝒚;𝜽)\log{\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{},{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}, we must pass samples 𝒙ˇ\bm{\check{x}} from the recognition model forward through the generative neural network, and backpropagate gradient values all the way into their inputs. Indeed, we can combine these two pairs of forward/backward passes: We can pass a set of observations 𝒚1,…,𝒚N\bm{y}_{1},\ldots,\bm{y}_{{N}} through the recognition networks; draw a set of latent samples 𝒙ˇ1,…,𝒙ˇN\bm{\check{x}}_{1},\ldots,\bm{\check{x}}_{{N}}, one for each observation33 3 It might seem that we need multiple samples of 𝑿ˇ{\bm{\check{X}}} for every sample of 𝒀{\bm{Y}}, and indeed we do need (roughly) quadratically more samples to estimate the joint distribution of 𝑿ˇ,𝒀{\bm{\check{X}}},{\bm{Y}} as opposed to just 𝒀{\bm{Y}}—say, L2L^{2}. But it is more efficient to have L2L^{2} different values of each of 𝑿ˇ,𝒀{\bm{\check{X}}},{\bm{Y}} rather than just LL different values for 𝒀{\bm{Y}} and L2L^{2} values of 𝑿ˇ{\bm{\check{X}}}; see Fig. 10.1.; pass these on through the generative neural network; and finally propagate gradients backward through the generative and recognition models. Note that backpropagation can simply ignore the sampling step.

But now note that along the backward pass through the generative network, we will compute precisely the quantities required for the M step gradient, ∂log⁡p^/∂𝜽\partial{\log\hat{p}}/\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{\theta}}} (recall Eq. 10.13 as well as our discussion of backprop, Section 7.1.3). Thus, we can compute all our gradients estimates, for both the E and M steps, in a single forward/backward pass. Notice that this entire process looks like a forward pass through a single neural network that maps each observation to itself—i.e., an autoencoder††margin: autoencoder —or, more precisely, to the log probability of that observation.

This suggests (although it does not require) updating the parameters of the generative and recongnition models together, rather than in alternation. This is the standard way to train such models.

A probabilistic autoencoder.

We observed above that this optimization procedure suggests thinking of the generative and recognition models together as a single, feedforward neural network (Fig. LABEL:fig:VAE). To emphasize this intuition, let us again reorganize the joint relative entropy:

equation (10.16) (10.16)
ℒ︀JRE⁢(𝜽,ϕ) . . =𝔼𝑿ˇ,𝒀[logpˇ(𝑿ˇ|𝒀;ϕ)p(𝒀)−logp^(𝑿ˇ,𝒀;𝜽)]=𝔼𝑿ˇ,𝒀[logpˇ(𝑿ˇ|𝒀;ϕ)−logp^(𝑿ˇ;𝜽)+logp(𝒀)−logp^(𝒀|𝑿ˇ;𝜽)]=DKL{pˇ(𝑿ˇ|𝒀;ϕ)∥p^(𝑿ˇ;𝜽)}+H(p⁢pˇ)⁢p^[𝒀|𝑿ˇ;ϕ,𝜽]−Hp[𝒀].\begin{split}\mathcal{L}_{\text{JRE}}(\bm{\theta},\bm{\phi})&{}\mathrel{\vbox{% \hbox{.}\hbox{.} }}=\mathbb{E}_{{\bm{\check{X}}}{},{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[% \log{\check{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}};% \bm{\phi}}\right)}{p\mathopen{}\mathclose{{}\left({\bm{Y}}}\right)}-\log{\hat{% p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}},{\bm{Y}};\bm{\theta}}\right)}% }\right]}\\ &{}=\mathbb{E}_{{\bm{\check{X}}}{},{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[% \log{\check{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}};% \bm{\phi}}\right)}-\log{\hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}};% \bm{\theta}}\right)}+\log{p\mathopen{}\mathclose{{}\left({\bm{Y}}}\right)}-% \log{\hat{p}\mathopen{}\mathclose{{}\left({\bm{Y}}\middle|{\bm{\check{X}}};\bm% {\theta}}\right)}}\right]}\\ &{}=\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check% {p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}};\bm{\phi}}% \right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}};\bm{% \theta}}\right)}}\right\}+{\text{H}_{(p\check{p})\hat{p}}{\mathopen{}% \mathclose{{}\left[{\bm{Y}}{}\middle|{\bm{\check{X}}}{};\bm{\phi},\bm{\theta}}% \right]}}-{\text{H}_{p}{\mathopen{}\mathclose{{}\left[{\bm{Y}}{}}\right]}}.% \end{split}

The second term, H(p⁢pˇ)⁢p^[𝒀|𝑿ˇ;ϕ,𝜽]{\text{H}_{(p\check{p})\hat{p}}{\mathopen{}\mathclose{{}\left[{\bm{Y}}{}% \middle|{\bm{\check{X}}}{};\bm{\phi},\bm{\theta}}\right]}}, can be interpreted as a reconstruction cost (see Section 8.3.2): the number of bits44 4 If a base-2 logarithm is used. required to encode the observations under the generative model, given latent states inferred with the recognition model. It measures the “lossiness” of the autoencoder. By itself, this term enforces a discriminative rather than generative cost. Note that, without further constraint, the reconstruction cost could be either greater or lower than the marginal entropy, Hp⁢[𝒀]{\text{H}_{p}{\mathopen{}\mathclose{{}\left[{\bm{Y}}{}}\right]}}; i.e., the final two terms could together be either positive or negative.55 5 For example, let Y{Y} be a biased coin (entropy less than 1 bit). A model could simply copy through the observations (reconstruction cost of 0 bits), or again predict heads and tails with equal probability (reconstruction cost of 1 bit).
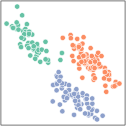
Figure 10.1: Two-step sampling. The isoprobability contours of a distribution are shown in green, along with samples drawn according to two different schemes: Given a budget of 64 samples, either draw 8 samples from the ordinate for each of 8 samples from the abscissa (orange); or draw a single sample from the ordinate for each of 64 samples from the abscissa (magenta).

We have previously (Section 8.3.2) interpreted the first term as the sum of a “code cost,” H(p⁢pˇ)⁢p^⁢[𝑿ˇ;ϕ,𝜽]{\text{H}_{(p\check{p})\hat{p}}{\mathopen{}\mathclose{{}\left[{\bm{\check{X}}}% {};\bm{\phi},\bm{\theta}}\right]}}, required to encode the latent states inferred by the recognition model; and −H(p⁢pˇ)[𝑿ˇ|𝒀;ϕ]-{\text{H}_{(p\check{p})}{\mathopen{}\mathclose{{}\left[{\bm{\check{X}}}{}% \middle|{\bm{Y}}{};\bm{\phi}}\right]}}, a regularizer that prevents the optimization from decreasing reconstruction and code costs merely by making recognition more confident. Alternatively, DKL{pˇ(𝑿ˇ|𝒀;ϕ)∥p^(𝑿ˇ;𝜽)}\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}};\bm{\phi}}% \right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}};\bm{% \theta}}\right)}}\right\} can be interpreted [39] as a regularizer that encourages the recognition posterior to resemble the generative prior. Intuitively, optimizing reconstruction cost obliges the emission density to “play well” with the recognition model (as well as to fit the observations); but to complete the generative model, we also need it to play well with the generative prior! This requires the recognition model and the generative prior to resemble each other. Indeed, the regularization that enforces this resemblance is the only place that the generative prior enters the loss.

It is important to realize that we do not expect this relative entropy to vanish in the optimal model, which will embody a compromise between this regularizer and the reconstruction cost (cf. Section 8.3.2). Instead, the joint relative entropy ℒ︀JRE\mathcal{L}_{\text{JRE}} vanishes at the optimum, so the most we can say is

DKL{pˇ(𝑿ˇ|𝒀;ϕ)∥p^(𝑿ˇ;𝜽)}=Hp[𝒀]−H(p⁢pˇ)⁢p^[𝒀|𝑿ˇ;ϕ,𝜽].\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}};\bm{\phi}}% \right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}};\bm{% \theta}}\right)}}\right\}={\text{H}_{p}{\mathopen{}\mathclose{{}\left[{\bm{Y}}% {}}\right]}}-{\text{H}_{(p\check{p})\hat{p}}{\mathopen{}\mathclose{{}\left[{% \bm{Y}}{}\middle|{\bm{\check{X}}}{};\bm{\phi},\bm{\theta}}\right]}}.

This equation tells us something intuitive: Since the left-hand side is non-negative, so must the right-hand side be; or in other words, the optimal reconstruction cost never exceeds the entropy of the data distribution.66 6 Returning to our previous example of a biased coin, we find that the optimal model should correctly identify heads-vs.-tails at least as frequently as the bias of the coin.

In the simplest VAEs, the generative priors are not parameterized, p^⁢(𝒙;𝜽)=p^⁢(𝒙){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}\right)}={\hat{p}% \mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}}\right)}, in which case the KL regularizer pushes the recognition model toward the generative prior but not vice versa. For the generative model considered in isolation, such a truly structureless prior distribution is desirable. The ideal latent variables are akin to the fundamental particles of physics: they should be as independent as possible, since any remaining structure is something that still needs to be explained. We prefer to let the emission, p^(𝒚|𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}% \right)}, capture all structure.

However, the recognition model makes additional demands on the generative prior: A simple calculation shows that if the recognition model, pˇ(𝒙|𝒚;ϕ){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\phi}}\right)}, matches the generative posterior, p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}, and the generative distribution, p^⁢(𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}\right)}, matches the data, p⁢(𝒚){p\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}}\right)}, then the generative prior, p^⁢(𝒙;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\theta}}\right)}, must match the “aggregated posterior,”

pˇ(𝒙;ϕ) . . =⟨pˇ(𝒙|𝒚;ϕ)⟩𝒚.{\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};\bm{\phi}}\right)}\mathrel{% \vbox{\hbox{.}\hbox{.} }}={\mathopen{}\mathclose{{}\left\langle{{\check{p}\mathopen{}\mathclose{{}% \left({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{x}}{}\middle|\bm{y};\bm{\phi}}\right)}}}\right\rangle_{\bm{y}{}}}.

In brief, for optimal generative and recognition models,

DKL⁡{pˇ⁢(𝑿ˇ;ϕ)∥p^⁢(𝑿ˇ;𝜽)}=0\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}% \mathopen{}\mathclose{{}\left({\bm{\check{X}}};\bm{\phi}}\right)}\middle\|{% \hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}};\bm{\theta}}\right)}}% \right\}=0

must hold. To understand this requirement, we yet again rewrite††margin: Exercise LABEL:ex: the joint relative entropy, Eq. 10.16, this time in terms of this relative entropy on “priors” [30]:

equation (10.17) (10.17)
ℒ︀JRE(𝜽,ϕ)=DKL{pˇ(𝑿ˇ;ϕ)∥p^(𝑿ˇ;𝜽)}+ℐ︀(𝑿ˇ;𝒀)+H(p⁢pˇ)⁢p^[𝒀|𝑿ˇ;ϕ,𝜽]−Hp[𝒀].\mathcal{L}_{\text{JRE}}(\bm{\theta},\bm{\phi})=\operatorname*{\text{D}_{\text% {KL}}}\mathopen{}\mathclose{{}\left\{{\check{p}\mathopen{}\mathclose{{}\left({% \bm{\check{X}}};\bm{\phi}}\right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}% \left({\bm{\check{X}}};\bm{\theta}}\right)}}\right\}+\mathcal{I}\mathopen{}% \mathclose{{}\left({\bm{\check{X}}};{\bm{Y}}}\right)+{\text{H}_{(p\check{p})% \hat{p}}{\mathopen{}\mathclose{{}\left[{\bm{Y}}{}\middle|{\bm{\check{X}}}{};% \bm{\phi},\bm{\theta}}\right]}}-{\text{H}_{p}{\mathopen{}\mathclose{{}\left[{% \bm{Y}}{}}\right]}}.

The penalty on information transmission prevents the reconstruction loss from being driven to zero, and vice versa. But the relative entropy in this equation—unlike the relative entropy in Eq. 10.16—does vanish in the optimal model.

10.2.1 Monte Carlo gradient estimators

In our discussion of probabilistic autoencoders thus far, we have considered only Gaussian recognition models (Eq. 10.12). This restriction allowed us to make use of the identities, Eqs. 10.3 and 10.4, to compute the M-step gradients efficiently (Eqs. 10.14 and 10.15). To understand what these identities bought us, and to see what other possibilities are available, let us pause to appraise our situation.

Ideally, the recognition model should be expressive enough to match the (uncomputable) generative posterior, p^(𝒙|𝒚;𝜽){\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\theta}}% \right)}, for some choice of recognition parameters, ϕ\bm{\phi}. Recall that the joint relative entropy (what we actually minimize) reduces to the marginal relative entropy (what we would like to minimize) precisely when this match is perfect.

Practically, the recognition model should not make the loss gradient hard to compute. The key constraint is that the joint relative entropy is an expectation under the recognition distribution, and we also need to compute gradients with respect to its parameters, ϕ\bm{\phi}. Recall that the joint relative entropy can be written the sum of the recognition entropy, the (negative) data entropy, and the joint cross entropy (see e.g. Eq. 8.9). Let us assume that the recognition entropy can be computed in closed form (it can for most distributions). And the data entropy is constant. That leaves the joint cross entropy, H(p⁢pˇ)⁢p^⁢[𝑿ˇ,𝒀;ϕ,𝜽]{\text{H}_{(p\check{p})\hat{p}}{\mathopen{}\mathclose{{}\left[{\bm{\check{X}}}% {},{\bm{Y}}{};\bm{\phi},\bm{\theta}}\right]}}. Note that in this term, the recognition parameters ϕ\bm{\phi} occur only in the expectation (the surprisal depends on the generative parameters 𝜽\bm{\theta} only). In fine, we need to compute

equation (10.18) (10.18)
dd⁢ϕ𝔼𝑿ˇ,𝒀[f(𝑿ˇ,𝒀)]=𝔼𝒀[dd⁢ϕ𝔼𝑿ˇ|𝒀[f(𝑿ˇ,𝒀)|𝒀]]\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\phi}}}\mathbb{E}_{{\bm{\check{X}}}{},{\bm{% Y}}{}}{\mathopen{}\mathclose{{}\left[f({\bm{\check{X}}},{\bm{Y}})}\right]}=% \mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\frac{\mathrm{d}{}}{% \mathrm{d}{\bm{\phi}}}\mathbb{E}_{{\bm{\check{X}}}{}|{\bm{Y}}}{\mathopen{}% \mathclose{{}\left[f({\bm{\check{X}}},{\bm{Y}})\middle|{\bm{Y}}{}}\right]}}% \right]}

where f⁢(𝑿^,𝒀^)=−log⁡p^⁢(𝑿^,𝒀^;𝜽)f({\bm{\hat{X}}},{\bm{\hat{Y}}})=-\log{\hat{p}\mathopen{}\mathclose{{}\left({% \bm{\hat{X}}},{\bm{\hat{Y}}};\bm{\theta}}\right)}, and the averaging distribution depends on ϕ\bm{\phi}. However, for functions ff that are at all complicated in 𝑿^{\bm{\hat{X}}}—for example, in generative models employing neural networks—the expectations will not be available in closed-form.

Our standard move in such situations is to approximate expectations with sample averages. But notice that in Eq. 10.18 we have a gradient of an expectation, not an expectation of a gradient. If we were simply to replace the expectation with a sample average, the gradient would have to pass into the sampling function. Instead, we need somehow to turn this gradient of an expection into an expected gradient, so that we can approximate it with an average gradient. We already saw one way to do so (Eqs. 10.3 and 10.4), but it works only with derivatives of Gaussian expectations. In formulating alternatives, we are concerned with the constraints that the usual desiderata for estimators—consistency, unbiasedness, low variance—impose on the class of tractable recognition distributions and on the dimensionality of the latent space.

The score-function gradient estimator.

Arguably the simplest and most general gradient estimator can be derived by passing the derivative directly into the integral defined by the expectation:

𝔼𝒀[dd⁢ϕ𝔼𝑿ˇ|𝒀[f(𝑿ˇ,𝒀)|𝒀]]=𝔼𝒀[∫𝒙ˇdd⁢ϕpˇ(𝒙ˇ|𝒀;ϕ)f(𝒙ˇ,𝒀)d𝒙ˇ]=𝔼𝒀[∫𝒙ˇpˇ(𝒙ˇ|𝒀;ϕ)dlogpˇ(𝒙ˇ|𝒀;ϕ)d⁢ϕf(𝒙ˇ,𝒀)d𝒙ˇ]=𝔼𝑿ˇ,𝒀⁢[dlogpˇ(𝑿ˇ|𝒀;ϕ)d⁢ϕ⁢f⁢(𝑿ˇ,𝒀)]≈⟨dlogpˇ(𝑿ˇ|𝒀;ϕ)d⁢ϕ⁢f⁢(𝑿ˇ,𝒀)⟩𝑿ˇ,𝒀,\begin{split}\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\frac{% \mathrm{d}{}}{\mathrm{d}{\bm{\phi}}}\mathbb{E}_{{\bm{\check{X}}}{}|{\bm{Y}}}{% \mathopen{}\mathclose{{}\left[f({\bm{\check{X}}},{\bm{Y}})\middle|{\bm{Y}}{}}% \right]}}\right]}&{}=\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[% \int_{\bm{\check{x}}{}}\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\phi}}}{\check{p}% \mathopen{}\mathclose{{}\left(\bm{\check{x}}\middle|{\bm{Y}};\bm{\phi}}\right)% }f(\bm{\check{x}},{\bm{Y}})\mathop{}\!\mathrm{d}{\bm{\check{x}}{}}}\right]}\\ &{}=\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\int_{\bm{\check{x}}% {}}{\check{p}\mathopen{}\mathclose{{}\left(\bm{\check{x}}\middle|{\bm{Y}};\bm{% \phi}}\right)}\frac{\mathrm{d}{\log{\check{p}\mathopen{}\mathclose{{}\left(\bm% {\check{x}}\middle|{\bm{Y}};\bm{\phi}}\right)}}}{\mathrm{d}{\bm{\phi}}}f(\bm{% \check{x}},{\bm{Y}})\mathop{}\!\mathrm{d}{\bm{\check{x}}{}}}\right]}\\ &{}=\mathbb{E}_{{\bm{\check{X}}}{},{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[% \frac{\mathrm{d}{\log{\check{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}% \middle|{\bm{Y}};\bm{\phi}}\right)}}}{\mathrm{d}{\bm{\phi}}}f({\bm{\check{X}}}% ,{\bm{Y}})}\right]}\\ &{}\approx{\mathopen{}\mathclose{{}\left\langle{\frac{\mathrm{d}{\log{\check{p% }\mathopen{}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}};\bm{\phi}}% \right)}}}{\mathrm{d}{\bm{\phi}}}f({\bm{\check{X}}},{\bm{Y}})}}\right\rangle_{% {\bm{\check{X}}}{},{\bm{Y}}{}}},\end{split}

where we have used Leibniz’s rule on the first line.77 7 This is generally licit for differentiable recognition distributions; for more precise conditions, see [47]. The point of the second line is to turn the expression back into an expectation under pˇ(𝒙|𝒚;ϕ){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\phi}}\right)}, in order to allow for a Monte Carlo estimate. The derivative on the final line is known as the score function††margin: score function , from which this gradient estimator inherits its name.

The score-function estimator is consistent and unbiased [47], but the variance scales poorly with latent dimension. This can be seen (e.g.) by considering the gradient estimator in the case of a factorial recognition distribution:

(∑kKdlogpˇ(xk|𝒚;ϕ)d⁢ϕ)⁢f⁢(𝒙,𝒚).\mathopen{}\mathclose{{}\left(\sum_{k}^{{K}}\frac{\mathrm{d}{\log{\check{p}% \mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}x_{k}}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\phi}}\right)% }}}{\mathrm{d}{\bm{\phi}}}}\right)f({\color[rgb]{.75,0,.25}\definecolor[named]% {pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}},{\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}).

Clearly, the variance of this estimator scales with the number of terms, K{K}, in the sum—even though dimensions may have little or no relationship with the cost ff. Therefore, in problems with large latent spaces, a prohibitively large number of samples must be drawn at each gradient step [39, 54].

On the other hand, the score-function estimator makes only very weak assumptions about pˇ(𝒙|𝒚;ϕ){\check{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}\middle|{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{};\bm{\phi}}\right)} and ff (the generative-model surprisal); and the cost of computing it scales (favorably) as 𝒪︀⁢(N⁢(D+L))\mathcal{O}({N}(D+L)), with DD and LL the dimensionality of the parameters ϕ\bm{\phi} and the cost of evaluating ff [47]. Furthermore, variance can often be reduced with the method of “control variates”; e.g., using as our estimator

⟨dlogpˇ(𝑿ˇ|𝒀)d⁢ϕ⁢(f⁢(𝑿ˇ,𝒀)−β)⟩𝑿ˇ,𝒀.{\mathopen{}\mathclose{{}\left\langle{\frac{\mathrm{d}{\log{\check{p}\mathopen% {}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}}}\right)}}}{\mathrm{d}{% \bm{\phi}}}\mathopen{}\mathclose{{}\left(f({\bm{\check{X}}},{\bm{Y}})-\beta}% \right)}}\right\rangle_{{\bm{\check{X}}}{},{\bm{Y}}{}}}.

Because the expected score is always zero (see Section B.2), this alteration does not change the expected value of the estimator, but can potentially lower its variance. More sophisticated control variates are also possible.

The pathwise gradient estimator.

Still, since we anticipate working with high-dimensional latent spaces, it behooves us to find an estimator whose variance is independent of this dimension. Here we exploit the fact that many continuous random variables with highly expressive distributions can be written as transformations of random variables with simpler, “base” distributions. This will allow us to separate parameter dependence (in the transformation) from the sampling procedure (for the base random variable). For example, any computationally tractable inverse CDF can be used to transform a uniformly distributed random variable into a random variable with the corresponding PDF:

equation (10.19) (10.19)
Zˇ∼𝒰︀(0,1),Xˇ=set−log(1−Zˇ)/λ= . . g(Zˇ,λ)⟹Xˇ∼Expo(λ).{\check{Z}}\sim\mathcal{U}\mathopen{}\mathclose{{}\left(0,1}\right),\hskip 18.% 06749pt{\check{X}}\stackrel{{\scriptstyle\text{set}}}{{=}}-\log\mathopen{}% \mathclose{{}\left(1-{\check{Z}}}\right)/\lambda=\mathrel{\vbox{\hbox{.}\hbox{% .} }}g({\check{Z}},\lambda)\implies{\check{X}}\sim\text{Expo}\mathopen{}% \mathclose{{}\left(\lambda}\right).

Similarly, random variables with distributions parameterized by location and scale can frequently be expressed as affine functions of random variables with the “standard” version of the distribution:

equation (10.20) (10.20)
𝒁ˇ∼𝒩︀(𝟎,𝐈),𝑿ˇ=set𝚺1/2𝒁ˇ+𝝁= . . 𝒈(𝒁ˇ,𝚺,𝝁)⟹𝑿ˇ∼𝒩︀(𝝁,𝚺).{\bm{\check{Z}}}\sim\mathcal{N}\mathopen{}\mathclose{{}\left(\bm{0},\>\mathbf{% I}}\right),\hskip 18.06749pt{\bm{\check{X}}}\stackrel{{\scriptstyle\text{set}}% }{{=}}\mathbf{\Sigma}^{1/2}{\bm{\check{Z}}}+\bm{\mu}=\mathrel{\vbox{\hbox{.}% \hbox{.} }}\bm{g}({\bm{\check{Z}}},\mathbf{\Sigma},\bm{\mu})\implies{\bm{\check{X}}}% \sim\mathcal{N}\mathopen{}\mathclose{{}\left(\bm{\mu},\>\mathbf{\Sigma}}\right).

More ambitiously, as long as the “path” 𝒈\bm{g} from auxiliary variables 𝒁ˇ{\bm{\check{Z}}} to latent variables 𝑿ˇ{\bm{\check{X}}} is invertible, we can construct complex distributions from simple ones with the change-of-variables formula:

equation (10.21) (10.21)
𝒁ˇ∼pˇ𝒁ˇ⁢(𝒛),𝑿ˇ=set𝒈⁢(𝒁ˇ,ϕ)⟹𝑿ˇ∼pˇ𝒁ˇ⁢(𝒈−1⁢(𝒙,ϕ))⁢|∂𝒈−1∂𝒙ˇT|.{\bm{\check{Z}}}\sim\check{p}_{{\bm{\check{Z}}}}\mathopen{}\mathclose{{}\left(% {\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{% z}}}\right),\hskip 18.06749pt{\bm{\check{X}}}\stackrel{{\scriptstyle\text{set}% }}{{=}}\bm{g}({\bm{\check{Z}}},\bm{\phi})\implies{\bm{\check{X}}}\sim\check{p}% _{{\bm{\check{Z}}}}\mathopen{}\mathclose{{}\left(\bm{g}^{-1}({\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}},\bm{\phi}% )}\right)\mathopen{}\mathclose{{}\left\lvert\frac{\partial{\bm{g}^{-1}}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{\check{x}}}}^{\text{T}}}}\right\rvert.

Indeed, the two preceding examples qualify as special cases of this technique. More subtle variations still on this theme allow for sampling from yet more distributions [39, 61, 47].

In all such cases, the function 𝒈⁢(𝒛,𝒚,ϕ)\bm{g}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{z}},{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{% rgb}{.75,0,.25}\bm{y}},\bm{\phi}) (notice that we have additionally allowed it to depend on 𝒚{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{% y}}) can be used in conjunction with the “law of the unconscious statistician” (LotUS) to remove the parameters from the expectation in Eq. 10.18:

𝔼𝒀[dd⁢ϕ𝔼𝑿ˇ|𝒀[f(𝑿ˇ,𝒀)|𝒀]]=𝔼𝒀[dd⁢ϕ𝔼𝒁ˇ|𝒀[f(𝒈(𝒁ˇ,𝒀,ϕ),𝒀)|𝒀]]=𝔼𝒀[𝔼𝒁ˇ|𝒀[d⁢𝒈Td⁢ϕ(𝒁ˇ,𝒀,ϕ)∂f∂𝒙ˇ(𝒈,𝒀)|𝒀]]≈⟨d⁢𝒈Td⁢ϕ⁢(𝒁ˇ,𝒀,ϕ)⁢∂f∂𝒙ˇ⁢(𝒈,𝒀)⟩𝒁ˇ,𝒀.\begin{split}\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\frac{% \mathrm{d}{}}{\mathrm{d}{\bm{\phi}}}\mathbb{E}_{{\bm{\check{X}}}{}|{\bm{Y}}}{% \mathopen{}\mathclose{{}\left[f({\bm{\check{X}}},{\bm{Y}})\middle|{\bm{Y}}{}}% \right]}}\right]}&{}=\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[% \frac{\mathrm{d}{}}{\mathrm{d}{\bm{\phi}}}\mathbb{E}_{{\bm{\check{Z}}}{}|{\bm{% Y}}}{\mathopen{}\mathclose{{}\left[f\mathopen{}\mathclose{{}\left(\bm{g}({\bm{% \check{Z}}},{\bm{Y}},\bm{\phi}),{\bm{Y}}}\right)\middle|{\bm{Y}}{}}\right]}}% \right]}\\ &{}=\mathbb{E}_{{\bm{Y}}{}}{\mathopen{}\mathclose{{}\left[\mathbb{E}_{{\bm{% \check{Z}}}{}|{\bm{Y}}}{\mathopen{}\mathclose{{}\left[\frac{\mathrm{d}{\bm{g}}% ^{\text{T}}}{\mathrm{d}{\bm{\phi}}}\mathopen{}\mathclose{{}\left({\bm{\check{Z% }}},{\bm{Y}},\bm{\phi}}\right)\frac{\partial{f}}{\partial{{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\check{x}}}}}% \mathopen{}\mathclose{{}\left(\bm{g},{\bm{Y}}}\right)\middle|{\bm{Y}}{}}\right% ]}}\right]}\\ &{}\approx{\mathopen{}\mathclose{{}\left\langle{\frac{\mathrm{d}{\bm{g}}^{% \text{T}}}{\mathrm{d}{\bm{\phi}}}\mathopen{}\mathclose{{}\left({\bm{\check{Z}}% },{\bm{Y}},\bm{\phi}}\right)\frac{\partial{f}}{\partial{{\color[rgb]{.75,0,.25% }\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\check{x}}}}}\mathopen% {}\mathclose{{}\left(\bm{g},{\bm{Y}}}\right)}}\right\rangle_{{\bm{\check{Z}}}{% },{\bm{Y}}{}}}.\end{split}

Crucially, under this formulation, the gradient passes into the cost function itself. Therefore, dimensions of the latent space that have little effect on the cost are guaranteed to have little effect on the estimator itself—in contrast to the score-function estimator. This is what allows low-variance estimates to be made even in high-dimensional spaces. The computational cost also turns out to be identical to that of the score-function estimator [47].

10.2.2 Examples

With this model, we have made considerable progress toward the goal of generating high-quality samples from complex distributions. …

Independent Gaussian random variables

Let us first proceed with the example we have been considering so far, a Gaussian recognition model, Eq. 10.12, with the additional constraint that the recognition covariance be diagonal:

𝚼⁢(𝒚,ϕ𝚼)=diag⁢(𝝊2⁢(𝒚,ϕ𝚼)).{\mathbf{{\Upsilon}}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor% }{rgb}{.75,0,.25}\bm{y}}{}{},\bm{\phi}_{\mathbf{{\Upsilon}}})}=\text{diag}% \mathopen{}\mathclose{{}\left({\bm{\upsilon}^{2}({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}{},\bm{\phi}_{% \mathbf{{\Upsilon}}})}}\right).

We will further assume that the generative model is also based on Gaussian distributions; in particular, let the generative model be

equation (10.22) (10.22)
p^⁢(𝒙)=𝒩︀⁢(𝟎,𝐈)\displaystyle{\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{}}\right)}=\mathcal% {N}\mathopen{}\mathclose{{}\left(\bm{0},\>\mathbf{I}}\right)
p^(𝒚|𝒙;𝜽)=𝒩︀(𝝁(𝒙,𝜽),α𝐈),\displaystyle{\hat{p}\mathopen{}\mathclose{{}\left({\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{y}}{}\middle|{\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}{};% \bm{\theta}}\right)}=\mathcal{N}\mathopen{}\mathclose{{}\left(\bm{\mu}({\color% [rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}},\bm% {\theta}),\>\alpha\mathbf{I}}\right),

with the mean 𝝁⁢(𝒙,𝜽)\bm{\mu}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{x}},\bm{\theta}) a flexible, parameterized function (neural networks) operating on its inputs 𝒙{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{% x}}. Then Eq. 10.14 simplifies (suppressing arguments) to

equation (10.23) (10.23)
d⁢ℒ︀JREd⁢ϕ𝝂≈⟨∂𝝂T∂ϕ𝝂⁢⟨𝑿ˇ+∂𝝁T∂𝒙⁢𝝁−𝒀α⟩𝑿ˇ|𝒀⟩𝒀=⟨∂𝝂T∂ϕ𝝂⁢(𝝂+⟨∂𝝁T∂𝒙⁢𝝁−𝒀α⟩𝑿ˇ|𝒀)⟩𝒀,\frac{\mathrm{d}{\mathcal{L}_{\text{JRE}}}}{\mathrm{d}{\bm{\phi}_{\bm{\nu}}}}% \approx{\mathopen{}\mathclose{{}\left\langle{\frac{\partial{\bm{\nu}}^{\text{T% }}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{\phi}_{\bm{\nu}}}}}{\mathopen{}\mathclose{{}\left\langle{{\bm{% \check{X}}}+\frac{\partial{\bm{\mu}{}}^{\text{T}}}{\partial{{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}{\color[rgb]{% .75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}}}}\frac{% \bm{\mu}{}-{\bm{Y}}}{\alpha}}}\right\rangle_{{\bm{\check{X}}}{}|{\bm{Y}}{}}}}}% \right\rangle_{{\bm{Y}}{}}}={\mathopen{}\mathclose{{}\left\langle{\frac{% \partial{\bm{\nu}}^{\text{T}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{\phi}_{\bm{\nu}}}}}\mathopen{}% \mathclose{{}\left(\bm{\nu}+{\mathopen{}\mathclose{{}\left\langle{\frac{% \partial{\bm{\mu}{}}^{\text{T}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}{\color[rgb]{.75,0,.25}\definecolor[% named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}}}}\frac{\bm{\mu}{}-{\bm{Y}}}{% \alpha}}}\right\rangle_{{\bm{\check{X}}}{}|{\bm{Y}}{}}}}\right)}}\right\rangle% _{{\bm{Y}}{}}},

and Eq. 10.15 becomes:

equation (10.24) (10.24)
d⁢ℒ︀JREd⁢ϕ𝚼i≈⟨12⁢tr⁢[(𝐈+⟨∑i∂2μi∂𝒙^⁢∂𝒙^T⁢μi−xiα+∂𝝁T∂𝒙⁢∂𝝁∂𝒙T⟩𝑿ˇ|𝒀−𝚼−1)⁢∂𝚼∂ϕ𝚼i]⟩𝒀\frac{\mathrm{d}{\mathcal{L}_{\text{JRE}}}}{\mathrm{d}{\phi_{\mathbf{{\Upsilon% }}}^{i}}}\approx{\mathopen{}\mathclose{{}\left\langle{\frac{1}{2}\text{tr}% \mathopen{}\mathclose{{}\left[\mathopen{}\mathclose{{}\left(\mathbf{I}+{% \mathopen{}\mathclose{{}\left\langle{\sum_{i}\frac{\partial^{2}{\mu_{i}}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{\hat{x}}}}\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{\hat{x}}}}^{\text{T}}}\frac{\mu_{i}-x_{i}}{% \alpha}+\frac{\partial{\bm{\mu}{}}^{\text{T}}}{\partial{{\color[rgb]{.75,0,.25% }\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}{\color[rgb]{.75,0,.25}% \definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}}}}\frac{\partial{% \bm{\mu}{}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\bm{x}}}}^{\text{T}}}}}\right\rangle_{{\bm{% \check{X}}}{}|{\bm{Y}}{}}}-\mathbf{{\Upsilon}}^{-1}}\right)\frac{\partial{% \mathbf{{\Upsilon}}}}{\partial{{\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}\phi_{\mathbf{{\Upsilon}}}^{i}}}}}\right]}}% \right\rangle_{{\bm{Y}}{}}}

These are the recognition-parameter gradients. The generative-parameter gradient, Eq. 10.13, becomes

d⁢ℒ︀JREd⁢𝜽≈⟨∂𝝁T∂𝜽⁢𝝁−𝒀α⟩𝑿ˇ,𝒀.\frac{\mathrm{d}{\mathcal{L}_{\text{JRE}}}}{\mathrm{d}{\bm{\theta}}}\approx{% \mathopen{}\mathclose{{}\left\langle{\frac{\partial{\bm{\mu}{}}^{\text{T}}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{\theta}}}}\frac{\bm{\mu}{}-{\bm{Y}}}{\alpha}}}\right\rangle_{{% \bm{\check{X}}}{},{\bm{Y}}{}}}.

The required neural-network gradients can be accumulated with forward and backward passes through the entire “autoencoder.” Parameters are then updated in proportion to the gradients in Eqs. 10.23, 10.24, and 10.2.2.

We have avoided the pathwise gradient estimator by employing the identities Eqs. 10.3 and 10.4. However, it is useful to consider the more generic approach. In particular, we will simply derive the loss function, since in modern software packages, this is handed directly to an automatic differentiator. Let us take the perspective of an autoencoder, i.e. the last line in Eq. 10.16. Anticipating, we calculate the log partition functions:

log⁡Zr=log⁡|τ⁢𝚼|1/2=K2⁢log⁡τ+12⁢∑kKlog⁡υk2log⁡Zg=log⁡|τ⁢𝐈|1/2=K2⁢log⁡τ\log Z_{\text{r}}=\log|\tau\mathbf{{\Upsilon}}|^{1/2}=\frac{{K}}{2}\log\tau+% \frac{1}{2}\sum_{k}^{{K}}\log\upsilon^{2}_{k}\qquad\log Z_{\text{g}}=\log|\tau% \mathbf{I}|^{1/2}=\frac{{K}}{2}\log\tau

Then the KL regularizer is

DKL{pˇ(𝑿ˇ|𝒀;ϕ)∥p^(𝑿ˇ;𝜽)}=⟨log⁡(ZgZr⁢exp⁡{−12⁢(𝝂−𝑿ˇ)T⁢𝚼−1⁢(𝝂−𝑿ˇ)+12⁢𝑿ˇT⁢𝑿ˇ})⟩𝑿ˇ,𝒀=⟨−12⁢∑kKlog⁡υk2−12⁢(𝝂−𝑿ˇ)T⁢𝚼−1⁢(𝝂−𝑿ˇ)+12⁢𝑿ˇT⁢𝑿ˇ⟩𝑿ˇ,𝒀=12⁢⟨−∑kKlog⁡υk2−tr⁢[𝚼⁢𝚼−1]+tr⁢[𝚼]+𝝂T⁢𝝂⟩𝒀=∑kK12⟨−logυk2−1+υk2+νk⟩2𝒀.\begin{split}\operatorname*{\text{D}_{\text{KL}}}\mathopen{}\mathclose{{}\left% \{{\check{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}\middle|{\bm{Y}};\bm% {\phi}}\right)}\middle\|{\hat{p}\mathopen{}\mathclose{{}\left({\bm{\check{X}}}% ;\bm{\theta}}\right)}}\right\}&{}={\mathopen{}\mathclose{{}\left\langle{\log% \mathopen{}\mathclose{{}\left(\frac{Z_{\text{g}}}{Z_{\text{r}}}\exp\mathopen{}% \mathclose{{}\left\{-\frac{1}{2}(\bm{\nu}-{\bm{\check{X}}})^{\text{T}}\mathbf{% {\Upsilon}}^{-1}(\bm{\nu}-{\bm{\check{X}}})+\frac{1}{2}{\bm{\check{X}}}^{\text% {T}}{\bm{\check{X}}}}\right\}}\right)}}\right\rangle_{{\bm{\check{X}}}{},{\bm{% Y}}{}}}\\ &{}={\mathopen{}\mathclose{{}\left\langle{-\frac{1}{2}\sum_{k}^{{K}}\log% \upsilon^{2}_{k}-\frac{1}{2}(\bm{\nu}-{\bm{\check{X}}})^{\text{T}}\mathbf{{% \Upsilon}}^{-1}(\bm{\nu}-{\bm{\check{X}}})+\frac{1}{2}{\bm{\check{X}}}^{\text{% T}}{\bm{\check{X}}}}}\right\rangle_{{\bm{\check{X}}}{},{\bm{Y}}{}}}\\ &{}=\frac{1}{2}{\mathopen{}\mathclose{{}\left\langle{-\sum_{k}^{{K}}\log% \upsilon^{2}_{k}-\text{tr}\mathopen{}\mathclose{{}\left[\mathbf{{\Upsilon}}% \mathbf{{\Upsilon}}^{-1}}\right]+\text{tr}\mathopen{}\mathclose{{}\left[% \mathbf{{\Upsilon}}}\right]+\bm{\nu}^{\text{T}}\bm{\nu}}}\right\rangle_{{\bm{Y% }}{}}}\\ &{}=\boxed{\sum_{k}^{{K}}\frac{1}{2}{\mathopen{}\mathclose{{}\left\langle{-% \log\upsilon^{2}_{k}-1+\upsilon^{2}_{k}+\nu_{k}{}^{2}}}\right\rangle_{{\bm{Y}}% {}}}}.\end{split}

In moving to the third line we twice used the identity Eq. B.16. Notice that this obviated the need for a sample average under the recognition distribution. Note also that the KL regularizer never depends on the generative-model parameters.

The reconstruction error is a cross entropy:

⟨−logp^(𝒀|𝑿ˇ;𝜽)⟩𝒀,𝑿ˇ=⟨log⁡|τ⁢α⁢𝐈|1/2+∥𝝁⁢(𝑿ˇ,𝜽)−𝒀∥22⁢α⟩𝑿ˇ,𝒀=12⁢⟨K⁢log⁡(τ⁢α)+∥𝝁⁢(𝑿ˇ,𝜽)−𝒀∥2α⟩𝑿ˇ,𝒀=12⁢⟨K⁢log⁡(τ⁢α)+∥𝝁⁢(𝚼⁢𝒁ˇ+𝝂,𝜽)−𝒀∥2α⟩𝒀,𝒁ˇ.\begin{split}{\mathopen{}\mathclose{{}\left\langle{-\log{\hat{p}\mathopen{}% \mathclose{{}\left({\bm{Y}}\middle|{\bm{\check{X}}};\bm{\theta}}\right)}}}% \right\rangle_{{\bm{Y}}{},{\bm{\check{X}}}{}}}&{}={\mathopen{}\mathclose{{}% \left\langle{\log|\tau\alpha\mathbf{I}|^{1/2}+\frac{\mathopen{}\mathclose{{}% \left\lVert\bm{\mu}({\bm{\check{X}}},\bm{\theta})-{\bm{Y}}}\right\rVert^{2}}{2% \alpha}}}\right\rangle_{{\bm{\check{X}}}{},{\bm{Y}}{}}}\\ &{}=\frac{1}{2}{\mathopen{}\mathclose{{}\left\langle{K\log\mathopen{}% \mathclose{{}\left(\tau\alpha}\right)+\frac{\mathopen{}\mathclose{{}\left% \lVert\bm{\mu}({\bm{\check{X}}},\bm{\theta})-{\bm{Y}}}\right\rVert^{2}}{\alpha% }}}\right\rangle_{{\bm{\check{X}}}{},{\bm{Y}}{}}}\\ &{}=\boxed{\frac{1}{2}{\mathopen{}\mathclose{{}\left\langle{K\log\mathopen{}% \mathclose{{}\left(\tau\alpha}\right)+\frac{\mathopen{}\mathclose{{}\left% \lVert\bm{\mu}(\mathbf{{\Upsilon}}{\bm{\check{Z}}}+\bm{\nu},\bm{\theta})-{\bm{% Y}}}\right\rVert^{2}}{\alpha}}}\right\rangle_{{\bm{Y}}{},{\bm{\check{Z}}}{}}}}% .\end{split}

We have reparameterized the average on the last line in anticipation of differentiating with respect to the parameters of 𝚼\mathbf{{\Upsilon}} and 𝝂\bm{\nu}.

Discrete VAEs with the Gumbel-Softmax trick

So far we have considered VAEs with Gaussian recognition distributions (Eq. 10.12), but what if we want discrete latent variables (as in e.g. the GMM)? As it stands, the pathwise gradient estimator will not work, because any function that discretizes will be flat almost everywhere. Any gradient that must pass through this function will be zero.

The most obvious workaround is to relax the discretization into some real-valued function, and we consider this first, although in a more subtle variation. Less obviously, we can employ a discretization that still passes real-valued information….

We begin simply with the relaxation itself and then bring in the VAE at the end. Suppose we want to draw categorical samples—which we interpret as one-hot vectors, 𝒚\bm{y}—according to real-valued natural parameters 𝜼\bm{\eta}. The standard way to do this is first to exponentiate (to make positive) and normalize the vector of natural parameters,

equation (10.25) (10.25)
∀l,Pr[Yl=1]=exp⁡{ηl}∑kKexp⁡{ηk}= . . σl(𝜼);\forall l,\quad\text{Pr}[{Y}_{l}=1]=\frac{\exp\mathopen{}\mathclose{{}\left\{% \eta_{l}}\right\}}{\sum_{k}^{K}\exp\mathopen{}\mathclose{{}\left\{\eta_{k}}% \right\}}=\mathrel{\vbox{\hbox{.}\hbox{.} }}\sigma_{l}(\bm{\eta});

then to draw a uniformly-distributed random variable, U∼𝒰︀⁢(0,1)U\sim\mathcal{U}\mathopen{}\mathclose{{}\left(0,1}\right); and finally to select the category at which the cumulative mass (under Eq. 10.25) first reaches UU. (Picturesquely, one can imagine dividing up the interval [0,1][0,1] into KK bins of widths given by the σl⁢(𝜼)\sigma_{l}(\bm{\eta}). The bin into which UU falls determines the category.)

However, now suppose we want to differentiate through the sampling operation. The inverse cumulative mass function is flat almost everywhere, so the derivative gives us no information. Perhaps we could smooth the CDF, although it is not obvious how we ought to.88 8 The two papers that proposed the Gumbel-softmax reparameterization do not even consider this possibility [45, 32]. Alternatively, perhaps there are other ways to sample from Eq. 10.25.

Gumbel perturbations.

Consider a set of KK independent, Gumbel-distributed, random variables, each with its own mean ηk\eta_{k}. The cumulative-distribution and probability-density functions of each such random variable are, respectively,

Fk⁢(g;ηk)=exp⁡{−e−(g−ηk)},\displaystyle F_{k}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}% {rgb}{.75,0,.25}g};\eta_{k})=\exp\mathopen{}\mathclose{{}\left\{-e^{-({\color[% rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{.75,0,.25}g}-\eta_{k})% }}\right\},
fk⁢(g;ηk)=exp⁡{−(g−ηk+e−(g−ηk))}.\displaystyle f_{k}({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}% {rgb}{.75,0,.25}g};\eta_{k})=\exp\mathopen{}\mathclose{{}\left\{-\mathopen{}% \mathclose{{}\left({\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{% rgb}{.75,0,.25}g}-\eta_{k}+e^{-({\color[rgb]{.75,0,.25}\definecolor[named]{% pgfstrokecolor}{rgb}{.75,0,.25}g}-\eta_{k})}}\right)}\right\}.

Equivalently, these random variables are produced by adding independent, zero-mean, Gumbel perturbations, 𝑮0{\bm{G}}_{0}, to our set of means: 𝑮=𝜼+𝑮0{\bm{G}}=\bm{\eta}+{\bm{G}}_{0}.

Distribution of the argmax.

If we know that Gl=g{G}_{l}=g, then the probability that Gl{G}_{l} is the largest Gumbel random variable is the probability that all the other variables are smaller than gg. In anticipation of what follows, we interpret the output of the argmax as a one-hot vector, and assign the symbol 𝝈0\bm{\sigma}_{0} to this vector-valued function:

𝒀 . . =argmaxk∈1,…,N{Gk}= . . 𝝈0(𝑮)=𝝈0(𝜼+𝑮0){\bm{Y}}\mathrel{\vbox{\hbox{.}\hbox{.} }}=\operatorname*{argmax}_{k\in{1,\ldots,N}}\mathopen{}\mathclose{{}\left\{{G}% _{k}}\right\}=\mathrel{\vbox{\hbox{.}\hbox{.} }}\bm{\sigma}_{0}({\bm{G}})=\bm{\sigma}_{0}(\bm{\eta}+{\bm{G}}_{0})

Then

Pr⁢[Yl=1|Gl=g]=Pr⁢[Gk⁢<g⁢∀k≠l|⁢Gl=g]=∏k≠lexp⁡{−e−(g−ηk)}.\text{Pr}[{Y}_{l}=1|{G}_{l}=g]=\text{Pr}[{G}_{k}<g\>\>\forall k\neq l|{G}_{l}=% g]=\prod_{k\neq l}\exp\mathopen{}\mathclose{{}\left\{-e^{-(g-\eta_{k})}}\right\}.

To convert this conditional probability into the marginal probability that Gl{G}_{l} is the largest, we simply multiply by the probability of Gl=g{G}_{l}=g and integrate over all possible values of gg:

equation (10.26) (10.26)
Pr⁢[Yl=1]=∫−∞∞∏k≠lexp⁡{−e−(g−ηk)}⁢exp⁡{−(g−ηl+e−(g−ηl))}⁢d⁢g=∫−∞∞∏kKexp⁡{−e−(g−ηk)}⁢exp⁡{−(g−ηl)}⁢d⁢g=exp⁡{ηl}⁢∫−∞∞exp⁡{−e−g⁢∑kKeηk}⁢exp⁡{−g}⁢dgt . . =e−g⟹=−exp⁡{ηl}⁢∫0∞exp⁡{−t⁢∑kKeηk}⁢dt=exp⁡{ηl}∑kKexp⁡{ηk}.\begin{split}\text{Pr}[{Y}_{l}=1]&{}=\int_{-\infty}^{\infty}\prod_{k\neq l}% \exp\mathopen{}\mathclose{{}\left\{-e^{-(g-\eta_{k})}}\right\}\exp\mathopen{}% \mathclose{{}\left\{-\mathopen{}\mathclose{{}\left(g-\eta_{l}+e^{-(g-\eta_{l})% }}\right)}\right\}\mathop{}\!\mathrm{d}{g}\\ &{}=\int_{-\infty}^{\infty}\prod_{k}^{K}\exp\mathopen{}\mathclose{{}\left\{-e^% {-(g-\eta_{k})}}\right\}\exp\mathopen{}\mathclose{{}\left\{-\mathopen{}% \mathclose{{}\left(g-\eta_{l}}\right)}\right\}\mathop{}\!\mathrm{d}{g}\\ &{}=\exp\mathopen{}\mathclose{{}\left\{\eta_{l}}\right\}\int_{-\infty}^{\infty% }\exp\mathopen{}\mathclose{{}\left\{-e^{-g}\sum_{k}^{K}e^{\eta_{k}}}\right\}% \exp\mathopen{}\mathclose{{}\left\{-g}\right\}\mathop{}\!\mathrm{d}{g}\\ t\mathrel{\vbox{\hbox{.}\hbox{.} }}=e^{-g}\implies&{}=-\exp\mathopen{}\mathclose{{}\left\{\eta_{l}}\right\}\int% _{0}^{\infty}\exp\mathopen{}\mathclose{{}\left\{-t\sum_{k}^{K}e^{\eta_{k}}}% \right\}\mathop{}\!\mathrm{d}{t}\\ &{}=\frac{\exp\mathopen{}\mathclose{{}\left\{\eta_{l}}\right\}}{\sum_{k}^{K}% \exp\mathopen{}\mathclose{{}\left\{\eta_{k}}\right\}}.\end{split}

In words, the probabilities of each Gumbel variate Gk{G}_{k} being the largest are given by the soft(arg)max function of their means. Eq. 10.26 matches Eq. 10.25, so we have arrived at an alternative method for drawing categorical samples: “Perturb” the vector 𝜼\bm{\eta} by independent, zero-mean Gumbel noise and then select the index of the largest element of the vector.

Relaxing the categorical distribution.

Unfortunately, the final step of the sampling procedure—the argmax—is not differentiable, so it seems we have made no progress over the standard sampling technique. On the other hand, it is more or less clear how to approximate the argmax—with a soft(arg)max, whose softness (ss) we can titrate:

equation (10.27) (10.27)
Yl≈exp⁡{Gl/s}∑kKexp⁡{Gk/s}=σl⁢(𝑮/s)=σl⁢(𝜼/s+𝑮0/s).{Y}_{l}\approx\frac{\exp\mathopen{}\mathclose{{}\left\{{G}_{l}/s}\right\}}{% \sum_{k}^{K}\exp\mathopen{}\mathclose{{}\left\{{G}_{k}/s}\right\}}=\sigma_{l}(% {\bm{G}}/s)=\sigma_{l}(\bm{\eta}/s+{\bm{G}}_{0}/s).

The softmax function is evidently differentiable:

d⁢σld⁢gm=σl⁢dd⁢gm⁢log⁡σl=σl⁢[1s⁢𝟙⁢[l=m]−1s⁢exp⁡{gm}∑kKexp⁡{gk/s}]=σl⁢1s⁢[𝟙⁢[l=m]−h~m].\frac{\mathrm{d}{\sigma_{l}}}{\mathrm{d}{g_{m}}}=\sigma_{l}\frac{\mathrm{d}{}}% {\mathrm{d}{g_{m}}}\log\sigma_{l}=\sigma_{l}\mathopen{}\mathclose{{}\left[% \frac{1}{s}\mathbbm{1}[l=m]-\frac{1}{s}\frac{\exp\mathopen{}\mathclose{{}\left% \{g_{m}}\right\}}{\sum_{k}^{K}\exp\mathopen{}\mathclose{{}\left\{g_{k}/s}% \right\}}}\right]=\sigma_{l}\frac{1}{s}\mathopen{}\mathclose{{}\left[\mathbbm{% 1}[l=m]-\tilde{h}_{m}}\right].

For very soft functions (s≫1s\gg 1), the gradient magnitudes are all manageable—indeed, less than 1—but the elements of 𝒀{\bm{Y}} become nearly equal (no matter the values of 𝜼\bm{\eta}), and the approximation to categorical random variables is bad. At s=1s=1, we are very nearly approximating 𝒀{\bm{Y}} by its mean, although because 𝜼\bm{\eta} is perturbed by Gumbel noise before passing through the softmax, this is not quite the case and samples will vary even for fixed 𝜼\bm{\eta}. For very hard functions (s≪1s\ll 1), 𝒀{\bm{Y}} approaches a one-hot vector—that is, an actual categorical sample. But in this same limit, lims→0\lim_{s\to 0}, the gradient becomes unbounded. In practice, then, the softness is typically decreased (starting from ∼\sim1) over the course of learning.

If we interpret Eq. 10.27 not as an approximation but as the definition of 𝒀{\bm{Y}}, then we can no longer say that 𝒀{\bm{Y}} is categorically distributed (except in the lims→0\lim_{s\to 0}, which we never reach). Instead, 𝒀{\bm{Y}} has a novel distribution, which its inventors call the “concrete” (a portmanteau of “continuous” and “discrete”) [45] or “Gumbel-softmax” [32] distribution. We will simply refer to it as the soft categorical distribution. What is the probability density for this distribution?

…

Using the Gumbel-softmax trick in a loss function.

Let the loss be an average over some function of 𝒀{\bm{Y}}, ℒ︀=⟨f⁢(𝒀)⟩𝒀\mathcal{L}={\mathopen{}\mathclose{{}\left\langle{f({\bm{Y}})}}\right\rangle_{% {\bm{Y}}{}}}, and the natural parameters be functions of some other parameters 𝜽\bm{\theta}, i.e. 𝜼=𝜼⁢(𝜽)\bm{\eta}=\bm{\eta}(\bm{\theta}). First, we reparameterize to allow the derivative to pass into the average:

d⁢ℒ︀d⁢𝜽=dd⁢𝜽⁢⟨f⁢(𝒀)⟩𝒀=dd⁢𝜽⁢⟨f⁢(𝝈0⁢(𝑮))⟩𝑮=dd⁢𝜽⁢⟨f⁢(𝝈0⁢(𝜼⁢(𝜽)+𝑮0))⟩𝑮0=⟨dd⁢𝜽⁢f⁢(𝝈0⁢(𝜼⁢(𝜽)+𝑮0))⟩𝑮0.\frac{\mathrm{d}{\mathcal{L}}}{\mathrm{d}{\bm{\theta}}}=\frac{\mathrm{d}{}}{% \mathrm{d}{\bm{\theta}}}{\mathopen{}\mathclose{{}\left\langle{f({\bm{Y}})}}% \right\rangle_{{\bm{Y}}{}}}=\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}}}{% \mathopen{}\mathclose{{}\left\langle{f(\bm{\sigma}_{0}({\bm{G}}))}}\right% \rangle_{{\bm{G}}{}}}=\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}}}{\mathopen{}% \mathclose{{}\left\langle{f(\bm{\sigma}_{0}(\bm{\eta}(\bm{\theta})+{\bm{G}}_{0% }))}}\right\rangle_{{\bm{G}}_{0}{}}}={\mathopen{}\mathclose{{}\left\langle{% \frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta}}}f(\bm{\sigma}_{0}(\bm{\eta}(\bm{% \theta})+{\bm{G}}_{0}))}}\right\rangle_{{\bm{G}}_{0}{}}}.

Now making the approximation,

d⁢ℒ︀d⁢𝜽≈⟨dd⁢𝜽⁢f⁢(𝝈⁢(𝜼⁢(𝜽)+𝑮0))⟩𝑮0=⟨d⁢𝜼Td⁢𝜽⁢∂𝝈T∂𝒈⁢(𝜼⁢(𝜽)+𝑮0)⁢∂f∂𝒚⁢(𝝈⁢(𝜼⁢(𝜽)+𝑮0))⟩𝑮0.\begin{split}\frac{\mathrm{d}{\mathcal{L}}}{\mathrm{d}{\bm{\theta}}}\approx{% \mathopen{}\mathclose{{}\left\langle{\frac{\mathrm{d}{}}{\mathrm{d}{\bm{\theta% }}}f(\bm{\sigma}(\bm{\eta}(\bm{\theta})+{\bm{G}}_{0}))}}\right\rangle_{{\bm{G}% }_{0}{}}}&{}={\mathopen{}\mathclose{{}\left\langle{\frac{\mathrm{d}{\bm{\eta}}% ^{\text{T}}}{\mathrm{d}{\bm{\theta}}}\frac{\partial{\bm{\sigma}}^{\text{T}}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{g}}}}(\bm{\eta}(\bm{\theta})+{\bm{G}}_{0})\frac{\partial{f}}{% \partial{{\color[rgb]{.75,0,.25}\definecolor[named]{pgfstrokecolor}{rgb}{% .75,0,.25}\bm{y}}}}(\bm{\sigma}(\bm{\eta}(\bm{\theta})+{\bm{G}}_{0}))}}\right% \rangle_{{\bm{G}}_{0}{}}}.\end{split}

Nomenclature.

This class of density estimator, with neural-network parameterized generative and recognition models, has come to be known as the variational autoencoder [39] We have seen how the model resembles the classical autoencoder. As for the term “variational,” it is something of a misnomer; we shall see how that term entered the literature shortly (Section 10.4).

In the VAE literature, the recognition model, or at least the deterministic neurl network that underlies it, is known as the encoder, since it “encodes” observations into a (latent) code. Likewise, the generative model (or again, the deterministic neural network that computes its moment parameters) is known as the decoder.

The “pathwise gradient estimator” that made this model practical has for its part come to be known as the “reparameterization trick.” I have followed the terminology of Mohamed and colleagues [47].